<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="4.4.1">Jekyll</generator><link href="https://strimzi.io/feed.xml" rel="self" type="application/atom+xml" /><link href="https://strimzi.io/" rel="alternate" type="text/html" /><updated>2026-09-05T14:47:04+00:00</updated><id>https://strimzi.io/feed.xml</id><title type="html">Strimzi - Apache Kafka on Kubernetes</title><subtitle>Strimzi provides a way to run an Apache Kafka cluster on Kubernetes in various deployment configurations.</subtitle><entry><title type="html">Video: What’s new in Strimzi 1.2.0</title><link href="https://strimzi.io/blog/2026/08/20/what-is-new-in-strimzi-1.2.0/" rel="alternate" type="text/html" title="Video: What’s new in Strimzi 1.2.0" /><published>2026-08-20T00:00:00+00:00</published><updated>2026-08-20T00:00:00+00:00</updated><id>https://strimzi.io/blog/2026/08/20/what-is-new-in-strimzi-1.2.0</id><content type="html" xml:base="https://strimzi.io/blog/2026/08/20/what-is-new-in-strimzi-1.2.0/"><![CDATA[<p>Strimzi 1.2.0 has been released with multiple new features and improvements.
As with previous releases, we created a video that introduces the main changes.
You can watch the video here or on our <a href="https://youtu.be/d1X-KB4hxGM">YouTube channel</a> and check the <a href="https://github.com/strimzi/strimzi-kafka-operator/releases/tag/1.2.0">release notes</a>.</p>

<!--more-->

<iframe width="560" height="315" src="https://www.youtube.com/embed/d1X-KB4hxGM" frameborder="0" allow="accelerometer; autoplay; encrypted-media; gyroscope; picture-in-picture" allowfullscreen=""></iframe>]]></content><author><name>Jakub Scholz</name></author><summary type="html"><![CDATA[Strimzi 1.2.0 has been released with multiple new features and improvements. As with previous releases, we created a video that introduces the main changes. You can watch the video here or on our YouTube channel and check the release notes.]]></summary></entry><entry><title type="html">Gateway API and TLSRoute support in Strimzi</title><link href="https://strimzi.io/blog/2026/07/09/gateway-api-tlsroute-support-in-strimzi/" rel="alternate" type="text/html" title="Gateway API and TLSRoute support in Strimzi" /><published>2026-07-09T00:00:00+00:00</published><updated>2026-07-09T00:00:00+00:00</updated><id>https://strimzi.io/blog/2026/07/09/gateway-api-tlsroute-support-in-strimzi</id><content type="html" xml:base="https://strimzi.io/blog/2026/07/09/gateway-api-tlsroute-support-in-strimzi/"><![CDATA[<p>Exposing Apache Kafka to clients running outside a Kubernetes cluster has always required some creative plumbing.
Over the years, Strimzi has accumulated four external listener types (<code class="language-plaintext highlighter-rouge">nodeport</code>, <code class="language-plaintext highlighter-rouge">loadbalancer</code>, <code class="language-plaintext highlighter-rouge">route</code> for OpenShift only, and <code class="language-plaintext highlighter-rouge">ingress</code>), and they each come with their own trade-offs.
The <code class="language-plaintext highlighter-rouge">ingress</code> type deserves special mention here, because it was recently deprecated and the story behind that deprecation is exactly what motivates this post.</p>

<p>The <code class="language-plaintext highlighter-rouge">type: ingress</code> listener relied on the <a href="https://github.com/kubernetes/ingress-nginx">Ingress NGINX Controller for Kubernetes</a>, a project that was <a href="https://kubernetes.io/blog/2025/11/11/ingress-nginx-retirement/">announced for retirement</a> by the Kubernetes community.
It was actually archived on the stage during KubeCon EU Amsterdam this year, and I was there!
With no future investment planned for that controller, building on top of it is no longer a good idea.
Fortunately, the Kubernetes ecosystem has a well-supported successor: the <strong>Gateway API</strong>.</p>

<p>Starting with Strimzi 1.1, the operator natively supports a new external listener type (<code class="language-plaintext highlighter-rouge">type: tlsroute</code>) based on the Kubernetes Gateway API and its <code class="language-plaintext highlighter-rouge">TLSRoute</code> resource.
In this post we will look at what the Gateway API is, why <code class="language-plaintext highlighter-rouge">TLSRoute</code> is the right fit for Kafka traffic, and then walk through a fully working example on <strong>minikube</strong> using <a href="https://gateway.envoyproxy.io/">Envoy Gateway</a> as the Gateway controller.</p>

<h3 id="from-ingress-to-gateway-api">From Ingress to Gateway API</h3>

<p>The <code class="language-plaintext highlighter-rouge">Ingress</code> resource was the original Kubernetes abstraction for north-south HTTP traffic.
It was never designed for non-HTTP protocols and, as a result, anyone trying to expose Kafka through it had to rely on vendor-specific annotations and implementation quirks.</p>

<p>The <a href="https://gateway-api.sigs.k8s.io/">Kubernetes Gateway API</a> was created to be a proper successor.
It is an official Kubernetes SIG project that defines a set of standard Custom Resource Definitions for routing L4 and L7 traffic.
It ships <em>only</em> the API specification; the actual data-plane work is delegated to Gateway controller implementations, of which there are <a href="https://gateway-api.sigs.k8s.io/implementations/">many</a>.
This clean separation means you can swap controllers without changing your application-level configuration.</p>

<p>The Gateway API introduces a hierarchy of resources:</p>

<ul>
  <li><strong><code class="language-plaintext highlighter-rouge">GatewayClass</code></strong>: a cluster-scoped resource that names a specific controller (comparable to <code class="language-plaintext highlighter-rouge">IngressClass</code>).</li>
  <li><strong><code class="language-plaintext highlighter-rouge">Gateway</code></strong>: an instance of a load balancer / proxy configured to handle traffic according to a <code class="language-plaintext highlighter-rouge">GatewayClass</code>.</li>
  <li><strong>Route resources</strong> (<code class="language-plaintext highlighter-rouge">HTTPRoute</code>, <code class="language-plaintext highlighter-rouge">GRPCRoute</code>, <code class="language-plaintext highlighter-rouge">TLSRoute</code>, <code class="language-plaintext highlighter-rouge">TCPRoute</code>, …): describe how traffic should be forwarded from the gateway to backend services.</li>
</ul>

<h3 id="why-tlsroute">Why TLSRoute?</h3>

<p>Kafka speaks its own binary protocol over TCP, not HTTP or gRPC, so <code class="language-plaintext highlighter-rouge">HTTPRoute</code> and <code class="language-plaintext highlighter-rouge">GRPCRoute</code> are immediately ruled out.
That leaves <code class="language-plaintext highlighter-rouge">TCPRoute</code> and <code class="language-plaintext highlighter-rouge">TLSRoute</code>.</p>

<p><code class="language-plaintext highlighter-rouge">TCPRoute</code> routes arbitrary TCP traffic based solely on the destination port.
This means you need a unique IP address <em>or</em> a unique port for every broker you want to expose, effectively 1 + N addresses/ports for a cluster with N brokers.
At any meaningful scale that quickly becomes unmanageable.</p>

<p><code class="language-plaintext highlighter-rouge">TLSRoute</code> solves this elegantly by using <strong>TLS-SNI</strong> (Server Name Indication) to route traffic.
Because Kafka clients always open a TLS-encrypted connection to the broker (when TLS is enabled), the client hostname is present in the TLS handshake <em>before</em> any Kafka protocol bytes are exchanged.
The gateway reads the SNI hostname and decides which backend service to forward the connection to.
This means that one gateway address and one port can serve the bootstrap endpoint <em>and</em> every individual broker, distinguished purely by hostname.</p>

<p><code class="language-plaintext highlighter-rouge">TLSRoute</code> moved to the <strong>Standard</strong> API channel in Gateway API v1.4 and got a stable <code class="language-plaintext highlighter-rouge">v1</code> API version in v1.5, making it a solid foundation to build on.</p>

<h3 id="how-strimzi-uses-tlsroute">How Strimzi uses TLSRoute</h3>

<p>When you configure a <code class="language-plaintext highlighter-rouge">type: tlsroute</code> listener, the Strimzi Cluster Operator takes care of all the Gateway API plumbing on your behalf:</p>

<ul>
  <li>A <strong>bootstrap service</strong> pointing to all brokers is created, along with a <strong>bootstrap <code class="language-plaintext highlighter-rouge">TLSRoute</code></strong> for the bootstrap hostname.</li>
  <li>A <strong>per-broker service</strong> and a <strong>per-broker <code class="language-plaintext highlighter-rouge">TLSRoute</code></strong> are created for each Kafka broker node, using the per-broker hostname.</li>
</ul>

<p>You only need to:</p>

<ol>
  <li>Deploy and configure a <code class="language-plaintext highlighter-rouge">Gateway</code> (using any Gateway API compatible controller).</li>
  <li>Reference that <code class="language-plaintext highlighter-rouge">Gateway</code> in your <code class="language-plaintext highlighter-rouge">Kafka</code> CR via the new <code class="language-plaintext highlighter-rouge">parentRefs</code> configuration field.</li>
</ol>

<p>Strimzi will create and keep the <code class="language-plaintext highlighter-rouge">TLSRoute</code> resources in sync.
This is especially useful when you combine <code class="language-plaintext highlighter-rouge">type: tlsroute</code> with horizontal auto-scaling of broker node pools: as brokers are added or removed, Strimzi automatically creates or deletes the corresponding <code class="language-plaintext highlighter-rouge">TLSRoute</code> resources.</p>

<blockquote>
  <p><strong>TLS passthrough vs. TLS termination</strong>: the TLS mode is configured on the <code class="language-plaintext highlighter-rouge">Gateway</code> listener, not in Strimzi. With TLS <em>passthrough</em>, the encrypted connection travels all the way to the Kafka broker; the broker’s certificate is what clients verify. This is what we use in this guide and is the most common setup. TLS <em>termination</em> at the gateway is also possible in principle, but Gateway API controller support for it is still emerging.</p>
</blockquote>

<h3 id="trying-it-on-minikube">Trying it on minikube</h3>

<p>The rest of this post is a step-by-step walkthrough for running the <code class="language-plaintext highlighter-rouge">type: tlsroute</code> listener on a laptop using minikube and Envoy Gateway.
At the end you will be able to produce and consume messages from outside the cluster using the standard Kafka client tools.</p>

<p>We assume minikube is already running locally. If you need to set it up first, follow the <a href="https://minikube.sigs.k8s.io/docs/start/">minikube getting started guide</a>.</p>

<h4 id="prerequisites">Prerequisites</h4>

<p>You will need the following tools installed:</p>

<ul>
  <li><a href="https://kubernetes.io/docs/tasks/tools/">kubectl</a></li>
  <li><a href="https://helm.sh/docs/intro/install/">Helm 3</a></li>
  <li>Strimzi 1.1.0+ installed in your cluster (the <a href="https://strimzi.io/quickstarts/">Quickstart</a> is the fastest path)</li>
  <li>Kafka CLI tools (<code class="language-plaintext highlighter-rouge">kafka-topics.sh</code>, <code class="language-plaintext highlighter-rouge">kafka-console-producer.sh</code>, <code class="language-plaintext highlighter-rouge">kafka-console-consumer.sh</code>); alternatively, you can run them from inside a broker pod</li>
</ul>

<h4 id="step-1-install-envoy-gateway">Step 1: Install Envoy Gateway</h4>

<p>Envoy Gateway ships with the Gateway API CRDs bundled, so there is no need to install them separately.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>helm <span class="nb">install </span>envoygateway oci://docker.io/envoyproxy/gateway-helm <span class="se">\</span>
  <span class="nt">-n</span> envoy-gateway-system <span class="nt">--create-namespace</span>

kubectl <span class="nb">wait</span> <span class="nt">--timeout</span><span class="o">=</span>5m <span class="nt">-n</span> envoy-gateway-system <span class="se">\</span>
  deployment/envoy-gateway <span class="nt">--for</span><span class="o">=</span><span class="nv">condition</span><span class="o">=</span>Available
</code></pre></div></div>

<p>Verify the installation and confirm that the Gateway API CRDs are present:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kubectl get pods <span class="nt">-n</span> envoy-gateway-system
kubectl get crd | <span class="nb">grep </span>gateway
</code></pre></div></div>

<p>You should see several CRDs including <code class="language-plaintext highlighter-rouge">gateways.gateway.networking.k8s.io</code> and <code class="language-plaintext highlighter-rouge">tlsroutes.gateway.networking.k8s.io</code>.</p>

<h4 id="step-2-create-the-envoyproxy-resource">Step 2: Create the EnvoyProxy resource</h4>

<p>The <code class="language-plaintext highlighter-rouge">EnvoyProxy</code> resource tells Envoy Gateway how to deploy the data-plane Envoy pods and what service type to use.
On minikube we use <code class="language-plaintext highlighter-rouge">LoadBalancer</code> and rely on <code class="language-plaintext highlighter-rouge">minikube tunnel</code> to expose it.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># envoy-proxy.yaml</span>
<span class="na">apiVersion</span><span class="pi">:</span> <span class="s">gateway.envoyproxy.io/v1alpha1</span>
<span class="na">kind</span><span class="pi">:</span> <span class="s">EnvoyProxy</span>
<span class="na">metadata</span><span class="pi">:</span>
  <span class="na">name</span><span class="pi">:</span> <span class="s">minikube-proxy</span>
  <span class="na">namespace</span><span class="pi">:</span> <span class="s">envoy-gateway-system</span>
<span class="na">spec</span><span class="pi">:</span>
  <span class="na">provider</span><span class="pi">:</span>
    <span class="na">type</span><span class="pi">:</span> <span class="s">Kubernetes</span>
    <span class="na">kubernetes</span><span class="pi">:</span>
      <span class="na">envoyService</span><span class="pi">:</span>
        <span class="na">type</span><span class="pi">:</span> <span class="s">LoadBalancer</span>
</code></pre></div></div>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kubectl apply <span class="nt">-f</span> envoy-proxy.yaml
</code></pre></div></div>

<h4 id="step-3-create-the-gatewayclass">Step 3: Create the GatewayClass</h4>

<p>A <code class="language-plaintext highlighter-rouge">GatewayClass</code> is a cluster-scoped resource that registers a specific Gateway controller with Kubernetes, much like <code class="language-plaintext highlighter-rouge">IngressClass</code> does for Ingress controllers.
Every <code class="language-plaintext highlighter-rouge">Gateway</code> you create later must reference a <code class="language-plaintext highlighter-rouge">GatewayClass</code>, which is how Kubernetes knows which controller should reconcile it.</p>

<p>The <code class="language-plaintext highlighter-rouge">controllerName</code> field identifies the Envoy Gateway controller, and the <code class="language-plaintext highlighter-rouge">parametersRef</code> points to the <code class="language-plaintext highlighter-rouge">EnvoyProxy</code> resource we created in the previous step so that the controller knows how to deploy the data-plane pods.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># gateway-class.yaml</span>
<span class="na">apiVersion</span><span class="pi">:</span> <span class="s">gateway.networking.k8s.io/v1</span>
<span class="na">kind</span><span class="pi">:</span> <span class="s">GatewayClass</span>
<span class="na">metadata</span><span class="pi">:</span>
  <span class="na">name</span><span class="pi">:</span> <span class="s">envoy-gateway</span>
<span class="na">spec</span><span class="pi">:</span>
  <span class="na">controllerName</span><span class="pi">:</span> <span class="s">gateway.envoyproxy.io/gatewayclass-controller</span>
  <span class="na">parametersRef</span><span class="pi">:</span>
    <span class="na">group</span><span class="pi">:</span> <span class="s">gateway.envoyproxy.io</span>
    <span class="na">kind</span><span class="pi">:</span> <span class="s">EnvoyProxy</span>
    <span class="na">name</span><span class="pi">:</span> <span class="s">minikube-proxy</span>
    <span class="na">namespace</span><span class="pi">:</span> <span class="s">envoy-gateway-system</span>
</code></pre></div></div>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kubectl apply <span class="nt">-f</span> gateway-class.yaml
kubectl get gatewayclass
</code></pre></div></div>

<p>The output should show the <code class="language-plaintext highlighter-rouge">GatewayClass</code> with <code class="language-plaintext highlighter-rouge">ACCEPTED</code> set to <code class="language-plaintext highlighter-rouge">True</code>, which means the Envoy Gateway controller has picked it up successfully.</p>

<h4 id="step-4-start-minikube-tunnel">Step 4: Start minikube tunnel</h4>

<p>The <code class="language-plaintext highlighter-rouge">LoadBalancer</code> service created for the gateway needs an external IP.
Open a <strong>new terminal</strong> and keep this command running throughout the session:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>minikube tunnel
</code></pre></div></div>

<p>You may be prompted for your <code class="language-plaintext highlighter-rouge">sudo</code> password.
Leave this terminal open and go back to your main terminal.</p>

<h4 id="step-5-create-the-gateway">Step 5: Create the Gateway</h4>

<p>A <code class="language-plaintext highlighter-rouge">Gateway</code> is an instance of a load balancer or proxy that listens for incoming traffic and routes it to backend services based on the attached route resources.
It references a <code class="language-plaintext highlighter-rouge">GatewayClass</code> (via <code class="language-plaintext highlighter-rouge">gatewayClassName</code>) so Envoy Gateway knows it is responsible for reconciling this resource and deploying the corresponding Envoy proxy pods.</p>

<p>The listener we define here is the entry point for all Kafka traffic:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">protocol: TLS</code> with <code class="language-plaintext highlighter-rouge">mode: Passthrough</code> tells the gateway to forward the raw TLS connection directly to the backend without terminating it. The TLS handshake happens end-to-end between the Kafka client and the Kafka broker.</li>
  <li><code class="language-plaintext highlighter-rouge">port: 8443</code> is the port on which the gateway will accept connections from outside the cluster.</li>
  <li><code class="language-plaintext highlighter-rouge">hostname: "*.kafka.local"</code> restricts this listener to SNI hostnames matching that wildcard, which covers both the bootstrap address and all per-broker addresses we will configure later.</li>
  <li><code class="language-plaintext highlighter-rouge">allowedRoutes.namespaces.from: All</code> permits <code class="language-plaintext highlighter-rouge">TLSRoute</code> resources from any namespace to attach to this listener, which is needed because Strimzi will create the routes in the Kafka cluster’s namespace.</li>
</ul>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># gateway.yaml</span>
<span class="na">apiVersion</span><span class="pi">:</span> <span class="s">gateway.networking.k8s.io/v1</span>
<span class="na">kind</span><span class="pi">:</span> <span class="s">Gateway</span>
<span class="na">metadata</span><span class="pi">:</span>
  <span class="na">name</span><span class="pi">:</span> <span class="s">envoy-gateway</span>
  <span class="na">namespace</span><span class="pi">:</span> <span class="s">envoy-gateway-system</span>
<span class="na">spec</span><span class="pi">:</span>
  <span class="na">gatewayClassName</span><span class="pi">:</span> <span class="s">envoy-gateway</span>
  <span class="na">listeners</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">tls-passthrough</span>
      <span class="na">protocol</span><span class="pi">:</span> <span class="s">TLS</span>
      <span class="na">port</span><span class="pi">:</span> <span class="m">8443</span>
      <span class="na">hostname</span><span class="pi">:</span> <span class="s2">"</span><span class="s">*.kafka.local"</span>
      <span class="na">tls</span><span class="pi">:</span>
        <span class="na">mode</span><span class="pi">:</span> <span class="s">Passthrough</span>
      <span class="na">allowedRoutes</span><span class="pi">:</span>
        <span class="na">namespaces</span><span class="pi">:</span>
          <span class="na">from</span><span class="pi">:</span> <span class="s">All</span>
</code></pre></div></div>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kubectl apply <span class="nt">-f</span> gateway.yaml
</code></pre></div></div>

<p>Wait a few seconds and then verify the Gateway is <code class="language-plaintext highlighter-rouge">PROGRAMMED</code>:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kubectl get gateway envoy-gateway <span class="nt">-n</span> envoy-gateway-system
</code></pre></div></div>

<p>If <code class="language-plaintext highlighter-rouge">PROGRAMMED</code> shows <code class="language-plaintext highlighter-rouge">False</code>, check that <code class="language-plaintext highlighter-rouge">minikube tunnel</code> is still running and that the LoadBalancer service has been assigned an <code class="language-plaintext highlighter-rouge">EXTERNAL-IP</code>:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kubectl get svc <span class="nt">-n</span> envoy-gateway-system
</code></pre></div></div>

<h4 id="step-6-configure-dns">Step 6: Configure DNS</h4>

<p>Because we are running on a laptop, there is no real DNS server that can resolve the Kafka hostnames to the gateway’s address.
We solve this by adding static entries to the local <code class="language-plaintext highlighter-rouge">/etc/hosts</code> file.
This is the same technique used when doing local Kubernetes development: map the hostnames you care about directly to the IP exposed by <code class="language-plaintext highlighter-rouge">minikube tunnel</code>.</p>

<p>The hostnames we need come from the Kafka listener configuration we will apply in Step 7.
The <code class="language-plaintext highlighter-rouge">bootstrap.host</code> field sets the bootstrap address (<code class="language-plaintext highlighter-rouge">bootstrap.kafka.local</code>), and the <code class="language-plaintext highlighter-rouge">hostTemplate</code> field defines the per-broker naming pattern (<code class="language-plaintext highlighter-rouge">broker-{nodeId}.kafka.local</code>), which for a three-broker cluster produces <code class="language-plaintext highlighter-rouge">broker-0.kafka.local</code>, <code class="language-plaintext highlighter-rouge">broker-1.kafka.local</code>, and <code class="language-plaintext highlighter-rouge">broker-2.kafka.local</code>.
We add all four entries now so that the cluster is reachable as soon as it finishes reconciling.</p>

<p>First, retrieve the external IP that was assigned to the gateway:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nv">GATEWAY_IP</span><span class="o">=</span><span class="si">$(</span>kubectl get gateway envoy-gateway <span class="nt">-n</span> envoy-gateway-system <span class="se">\</span>
  <span class="nt">-o</span> <span class="nv">jsonpath</span><span class="o">=</span><span class="s1">'{.status.addresses[0].value}'</span><span class="si">)</span>
<span class="nb">echo</span> <span class="nv">$GATEWAY_IP</span>
</code></pre></div></div>

<p>Add entries to <code class="language-plaintext highlighter-rouge">/etc/hosts</code> so your laptop can resolve the Kafka hostnames:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">sudo tee</span> <span class="nt">-a</span> /etc/hosts <span class="o">&lt;&lt;</span><span class="no">EOF</span><span class="sh">
</span><span class="k">${</span><span class="nv">GATEWAY_IP</span><span class="k">}</span><span class="sh"> bootstrap.kafka.local
</span><span class="k">${</span><span class="nv">GATEWAY_IP</span><span class="k">}</span><span class="sh"> broker-0.kafka.local
</span><span class="k">${</span><span class="nv">GATEWAY_IP</span><span class="k">}</span><span class="sh"> broker-1.kafka.local
</span><span class="k">${</span><span class="nv">GATEWAY_IP</span><span class="k">}</span><span class="sh"> broker-2.kafka.local
</span><span class="no">EOF
</span></code></pre></div></div>

<p>You can verify that DNS resolves correctly with:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ping <span class="nt">-c</span> 1 bootstrap.kafka.local
</code></pre></div></div>

<p>Note that the ping itself will likely time out (the gateway only listens on TCP); what matters is that the hostname resolves to the right IP.</p>

<h4 id="step-7-deploy-the-kafka-cluster-with-a-tlsroute-listener">Step 7: Deploy the Kafka cluster with a tlsroute listener</h4>

<p>We assume the Strimzi Cluster Operator is installed in the <code class="language-plaintext highlighter-rouge">kafka</code> namespace and we will deploy the Kafka cluster there as well.</p>

<p>Create the <code class="language-plaintext highlighter-rouge">Kafka</code> and <code class="language-plaintext highlighter-rouge">KafkaNodePool</code> resources.
The key part is the <code class="language-plaintext highlighter-rouge">external</code> listener of <code class="language-plaintext highlighter-rouge">type: tlsroute</code>, which instructs Strimzi to create <code class="language-plaintext highlighter-rouge">TLSRoute</code> resources instead of managing <code class="language-plaintext highlighter-rouge">Ingress</code> or <code class="language-plaintext highlighter-rouge">LoadBalancer</code> objects itself.</p>

<p>A few fields in the listener configuration are worth calling out:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">parentRefs</code> points to the <code class="language-plaintext highlighter-rouge">Gateway</code> resource created in Step 5. This is how Strimzi knows which gateway to attach the <code class="language-plaintext highlighter-rouge">TLSRoute</code> resources to.</li>
  <li><code class="language-plaintext highlighter-rouge">bootstrap.host</code> sets the hostname advertised to Kafka clients for the initial connection.</li>
  <li><code class="language-plaintext highlighter-rouge">hostTemplate</code> defines the per-broker hostname pattern. The <code class="language-plaintext highlighter-rouge">{nodeId}</code> placeholder is replaced by the actual broker node ID at runtime.</li>
  <li><code class="language-plaintext highlighter-rouge">advertisedPortTemplate: 8443</code> fixes the advertised port to <code class="language-plaintext highlighter-rouge">8443</code> for every broker, matching the single port our gateway listener is configured on.</li>
</ul>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># kafka-cluster.yaml</span>
<span class="na">apiVersion</span><span class="pi">:</span> <span class="s">kafka.strimzi.io/v1</span>
<span class="na">kind</span><span class="pi">:</span> <span class="s">KafkaNodePool</span>
<span class="na">metadata</span><span class="pi">:</span>
  <span class="na">name</span><span class="pi">:</span> <span class="s">controller</span>
  <span class="na">labels</span><span class="pi">:</span>
    <span class="na">strimzi.io/cluster</span><span class="pi">:</span> <span class="s">my-cluster</span>
<span class="na">spec</span><span class="pi">:</span>
  <span class="na">replicas</span><span class="pi">:</span> <span class="m">3</span>
  <span class="na">roles</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="s">controller</span>
  <span class="na">storage</span><span class="pi">:</span>
    <span class="na">type</span><span class="pi">:</span> <span class="s">jbod</span>
    <span class="na">volumes</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="na">id</span><span class="pi">:</span> <span class="m">0</span>
        <span class="na">type</span><span class="pi">:</span> <span class="s">ephemeral</span>
        <span class="na">kraftMetadata</span><span class="pi">:</span> <span class="s">shared</span>
<span class="nn">---</span>
<span class="na">apiVersion</span><span class="pi">:</span> <span class="s">kafka.strimzi.io/v1</span>
<span class="na">kind</span><span class="pi">:</span> <span class="s">KafkaNodePool</span>
<span class="na">metadata</span><span class="pi">:</span>
  <span class="na">name</span><span class="pi">:</span> <span class="s">broker</span>
  <span class="na">labels</span><span class="pi">:</span>
    <span class="na">strimzi.io/cluster</span><span class="pi">:</span> <span class="s">my-cluster</span>
<span class="na">spec</span><span class="pi">:</span>
  <span class="na">replicas</span><span class="pi">:</span> <span class="m">3</span>
  <span class="na">roles</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="s">broker</span>
  <span class="na">storage</span><span class="pi">:</span>
    <span class="na">type</span><span class="pi">:</span> <span class="s">jbod</span>
    <span class="na">volumes</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="na">id</span><span class="pi">:</span> <span class="m">0</span>
        <span class="na">type</span><span class="pi">:</span> <span class="s">ephemeral</span>
        <span class="na">kraftMetadata</span><span class="pi">:</span> <span class="s">shared</span>
<span class="nn">---</span>
<span class="na">apiVersion</span><span class="pi">:</span> <span class="s">kafka.strimzi.io/v1</span>
<span class="na">kind</span><span class="pi">:</span> <span class="s">Kafka</span>
<span class="na">metadata</span><span class="pi">:</span>
  <span class="na">name</span><span class="pi">:</span> <span class="s">my-cluster</span>
<span class="na">spec</span><span class="pi">:</span>
  <span class="na">kafka</span><span class="pi">:</span>
    <span class="na">version</span><span class="pi">:</span> <span class="s">4.3.0</span>
    <span class="na">metadataVersion</span><span class="pi">:</span> <span class="s">4.3-IV0</span>
    <span class="na">listeners</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">plain</span>
        <span class="na">port</span><span class="pi">:</span> <span class="m">9092</span>
        <span class="na">type</span><span class="pi">:</span> <span class="s">internal</span>
        <span class="na">tls</span><span class="pi">:</span> <span class="kc">false</span>
      <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">tls</span>
        <span class="na">port</span><span class="pi">:</span> <span class="m">9093</span>
        <span class="na">type</span><span class="pi">:</span> <span class="s">internal</span>
        <span class="na">tls</span><span class="pi">:</span> <span class="kc">true</span>
      <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">external</span>
        <span class="na">port</span><span class="pi">:</span> <span class="m">9094</span>
        <span class="na">type</span><span class="pi">:</span> <span class="s">tlsroute</span>
        <span class="na">tls</span><span class="pi">:</span> <span class="kc">true</span>
        <span class="na">configuration</span><span class="pi">:</span>
          <span class="na">bootstrap</span><span class="pi">:</span>
            <span class="na">host</span><span class="pi">:</span> <span class="s">bootstrap.kafka.local</span>
          <span class="na">parentRefs</span><span class="pi">:</span>
            <span class="pi">-</span> <span class="na">kind</span><span class="pi">:</span> <span class="s">Gateway</span>
              <span class="na">group</span><span class="pi">:</span> <span class="s">gateway.networking.k8s.io</span>
              <span class="na">name</span><span class="pi">:</span> <span class="s">envoy-gateway</span>
              <span class="na">namespace</span><span class="pi">:</span> <span class="s">envoy-gateway-system</span>
          <span class="na">hostTemplate</span><span class="pi">:</span> <span class="s">broker-{nodeId}.kafka.local</span>
          <span class="na">advertisedPortTemplate</span><span class="pi">:</span> <span class="s2">"</span><span class="s">8443"</span>
    <span class="na">config</span><span class="pi">:</span>
      <span class="na">offsets.topic.replication.factor</span><span class="pi">:</span> <span class="m">3</span>
      <span class="na">transaction.state.log.replication.factor</span><span class="pi">:</span> <span class="m">3</span>
      <span class="na">transaction.state.log.min.isr</span><span class="pi">:</span> <span class="m">2</span>
      <span class="na">default.replication.factor</span><span class="pi">:</span> <span class="m">3</span>
      <span class="na">min.insync.replicas</span><span class="pi">:</span> <span class="m">2</span>
  <span class="na">entityOperator</span><span class="pi">:</span>
    <span class="na">topicOperator</span><span class="pi">:</span> <span class="pi">{}</span>
    <span class="na">userOperator</span><span class="pi">:</span> <span class="pi">{}</span>
</code></pre></div></div>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kubectl apply <span class="nt">-f</span> kafka-cluster.yaml <span class="nt">-n</span> kafka
kubectl <span class="nb">wait </span>kafka/my-cluster <span class="nt">-n</span> kafka <span class="nt">--for</span><span class="o">=</span><span class="nv">condition</span><span class="o">=</span>Ready <span class="nt">--timeout</span><span class="o">=</span>300s
</code></pre></div></div>

<p>Once the cluster is ready, verify that Strimzi has created the <code class="language-plaintext highlighter-rouge">TLSRoute</code> resources automatically in the <code class="language-plaintext highlighter-rouge">kafka</code> namespace:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kubectl get tlsroute <span class="nt">-n</span> kafka
</code></pre></div></div>

<p>You should see one bootstrap route and one route per broker:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>NAME                              HOSTNAMES                        AGE
my-cluster-kafka-bootstrap        ["bootstrap.kafka.local"]        2m
my-cluster-broker-0               ["broker-0.kafka.local"]         2m
my-cluster-broker-1               ["broker-1.kafka.local"]         2m
my-cluster-broker-2               ["broker-2.kafka.local"]         2m
</code></pre></div></div>

<blockquote>
  <p><strong>Tip</strong>: If the <code class="language-plaintext highlighter-rouge">TLSRoute</code> resources are not created and the Cluster Operator logs show <code class="language-plaintext highlighter-rouge">The Gateway API TLSRoute resource is not available in this Kubernetes cluster</code>, the operator was started before the Gateway API CRDs were installed. Simply restart it (replace <code class="language-plaintext highlighter-rouge">&lt;operator-namespace&gt;</code> with the namespace where Strimzi is installed, e.g. <code class="language-plaintext highlighter-rouge">strimzi</code> if you used the Quickstart):</p>
  <div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kubectl rollout restart deployment strimzi-cluster-operator <span class="nt">-n</span> &lt;operator-namespace&gt;
</code></pre></div>  </div>
</blockquote>

<h4 id="step-8-test-the-connection">Step 8: Test the connection</h4>

<p>Before connecting Kafka clients, we need to extract the cluster CA certificate that Strimzi generated for the cluster.
Clients must trust this CA to be able to establish a TLS connection to the brokers.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kubectl get secret my-cluster-cluster-ca-cert <span class="nt">-n</span> kafka <span class="se">\</span>
  <span class="nt">-o</span> <span class="nv">jsonpath</span><span class="o">=</span><span class="s1">'{.data.ca\.crt}'</span> | <span class="nb">base64</span> <span class="nt">-d</span> <span class="o">&gt;</span> ca.crt
</code></pre></div></div>

<p>With the CA certificate in hand, do a quick sanity check with OpenSSL to verify the TLS passthrough is working end to end:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>openssl s_client <span class="nt">-connect</span> broker-0.kafka.local:8443 <span class="se">\</span>
  <span class="nt">-servername</span> broker-0.kafka.local <span class="nt">-showcerts</span>
</code></pre></div></div>

<p>You should see <code class="language-plaintext highlighter-rouge">CONNECTED</code> and the broker certificate chain.
A <code class="language-plaintext highlighter-rouge">Verify return code: 19 (self-signed certificate in certificate chain)</code> is expected; the important thing is that the TLS handshake completes successfully.</p>

<p>Now test with the Kafka CLI tools.
All commands need to know the bootstrap address and that TLS is required, so start by creating a client properties file that every tool will share via <code class="language-plaintext highlighter-rouge">--command-config</code> or <code class="language-plaintext highlighter-rouge">--producer.config</code> / <code class="language-plaintext highlighter-rouge">--consumer.config</code>:</p>

<div class="language-properties highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># client-ssl.properties
</span><span class="py">bootstrap.servers</span><span class="p">=</span><span class="s">bootstrap.kafka.local:8443</span>
<span class="py">security.protocol</span><span class="p">=</span><span class="s">SSL</span>
<span class="py">ssl.truststore.type</span><span class="p">=</span><span class="s">PEM</span>
<span class="py">ssl.truststore.location</span><span class="p">=</span><span class="s">ca.crt</span>
</code></pre></div></div>

<p>The <code class="language-plaintext highlighter-rouge">ssl.truststore.location</code> points to the <code class="language-plaintext highlighter-rouge">ca.crt</code> file we just extracted.
Using <code class="language-plaintext highlighter-rouge">ssl.truststore.type=PEM</code> means we can pass the certificate file directly without converting it to a Java keystore first.</p>

<p>First, verify that the client can reach the cluster and list topics.
At this point the list will be empty, but a successful response confirms that the bootstrap connection and broker metadata exchange are working correctly:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kafka-topics.sh <span class="nt">--bootstrap-server</span> bootstrap.kafka.local:8443 <span class="se">\</span>
  <span class="nt">--command-config</span> client-ssl.properties <span class="se">\</span>
  <span class="nt">--list</span>
</code></pre></div></div>

<p>Next, create a test topic with three partitions and a replication factor of three, one replica per broker:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kafka-topics.sh <span class="nt">--bootstrap-server</span> bootstrap.kafka.local:8443 <span class="se">\</span>
  <span class="nt">--command-config</span> client-ssl.properties <span class="se">\</span>
  <span class="nt">--create</span> <span class="nt">--topic</span> test-topic <span class="se">\</span>
  <span class="nt">--partitions</span> 3 <span class="nt">--replication-factor</span> 3
</code></pre></div></div>

<p>With the topic in place, open an interactive producer session and type a few messages, pressing Enter after each one.
Press <code class="language-plaintext highlighter-rouge">Ctrl+C</code> when you are done to close the producer:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kafka-console-producer.sh <span class="nt">--bootstrap-server</span> bootstrap.kafka.local:8443 <span class="se">\</span>
  <span class="nt">--producer</span>.config client-ssl.properties <span class="se">\</span>
  <span class="nt">--topic</span> test-topic
</code></pre></div></div>

<p>Finally, start a consumer reading from the beginning of the topic.
It should print every message you just produced, which confirms that the per-broker <code class="language-plaintext highlighter-rouge">TLSRoute</code> resources are working correctly.
Each message was written to a specific broker and the consumer was able to reach that broker individually through its own dedicated route:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kafka-console-consumer.sh <span class="nt">--bootstrap-server</span> bootstrap.kafka.local:8443 <span class="se">\</span>
  <span class="nt">--consumer</span>.config client-ssl.properties <span class="se">\</span>
  <span class="nt">--topic</span> test-topic <span class="se">\</span>
  <span class="nt">--from-beginning</span>
</code></pre></div></div>

<p>Press <code class="language-plaintext highlighter-rouge">Ctrl+C</code> to stop the consumer once you have seen all the messages.</p>

<h3 id="conclusion">Conclusion</h3>

<p>The new <code class="language-plaintext highlighter-rouge">type: tlsroute</code> listener brings first-class Gateway API support to Strimzi.
It fills the gap left by the deprecated <code class="language-plaintext highlighter-rouge">type: ingress</code> listener and does so on a stable, vendor-neutral standard that has broad ecosystem support.</p>

<p>From a user perspective, the configuration is straightforward: bring your own <code class="language-plaintext highlighter-rouge">Gateway</code>, point Strimzi at it via <code class="language-plaintext highlighter-rouge">parentRefs</code>, and Strimzi takes care of creating and maintaining the <code class="language-plaintext highlighter-rouge">TLSRoute</code> resources, including as brokers are scaled up or down.</p>

<p>From a protocol perspective, TLS-SNI-based routing gives you the clean one-address-one-port topology that is so important for the Kafka protocol, without the complexity of managing one unique IP per broker that <code class="language-plaintext highlighter-rouge">TCPRoute</code> would require.</p>

<p>If you are currently using <code class="language-plaintext highlighter-rouge">type: ingress</code> and wondering what to migrate to, <code class="language-plaintext highlighter-rouge">type: tlsroute</code> is the answer.
Any <a href="https://gateway-api.sigs.k8s.io/implementations/">Gateway API compatible controller</a> will work; in this post we used Envoy Gateway, but you could equally use Cilium Gateway API, Istio, NGINX Gateway Fabric, or any other implementation you already have in your cluster.</p>

<p>For more background on the design decisions behind this feature, have a look at <a href="https://github.com/strimzi/proposals/blob/main/136-tls-route-listener.md">Strimzi proposal #136</a>.</p>]]></content><author><name>Paolo Patierno</name></author><summary type="html"><![CDATA[Exposing Apache Kafka to clients running outside a Kubernetes cluster has always required some creative plumbing. Over the years, Strimzi has accumulated four external listener types (nodeport, loadbalancer, route for OpenShift only, and ingress), and they each come with their own trade-offs. The ingress type deserves special mention here, because it was recently deprecated and the story behind that deprecation is exactly what motivates this post. The type: ingress listener relied on the Ingress NGINX Controller for Kubernetes, a project that was announced for retirement by the Kubernetes community. It was actually archived on the stage during KubeCon EU Amsterdam this year, and I was there! With no future investment planned for that controller, building on top of it is no longer a good idea. Fortunately, the Kubernetes ecosystem has a well-supported successor: the Gateway API. Starting with Strimzi 1.1, the operator natively supports a new external listener type (type: tlsroute) based on the Kubernetes Gateway API and its TLSRoute resource. In this post we will look at what the Gateway API is, why TLSRoute is the right fit for Kafka traffic, and then walk through a fully working example on minikube using Envoy Gateway as the Gateway controller. From Ingress to Gateway API The Ingress resource was the original Kubernetes abstraction for north-south HTTP traffic. It was never designed for non-HTTP protocols and, as a result, anyone trying to expose Kafka through it had to rely on vendor-specific annotations and implementation quirks. The Kubernetes Gateway API was created to be a proper successor. It is an official Kubernetes SIG project that defines a set of standard Custom Resource Definitions for routing L4 and L7 traffic. It ships only the API specification; the actual data-plane work is delegated to Gateway controller implementations, of which there are many. This clean separation means you can swap controllers without changing your application-level configuration. The Gateway API introduces a hierarchy of resources: GatewayClass: a cluster-scoped resource that names a specific controller (comparable to IngressClass). Gateway: an instance of a load balancer / proxy configured to handle traffic according to a GatewayClass. Route resources (HTTPRoute, GRPCRoute, TLSRoute, TCPRoute, …): describe how traffic should be forwarded from the gateway to backend services. Why TLSRoute? Kafka speaks its own binary protocol over TCP, not HTTP or gRPC, so HTTPRoute and GRPCRoute are immediately ruled out. That leaves TCPRoute and TLSRoute. TCPRoute routes arbitrary TCP traffic based solely on the destination port. This means you need a unique IP address or a unique port for every broker you want to expose, effectively 1 + N addresses/ports for a cluster with N brokers. At any meaningful scale that quickly becomes unmanageable. TLSRoute solves this elegantly by using TLS-SNI (Server Name Indication) to route traffic. Because Kafka clients always open a TLS-encrypted connection to the broker (when TLS is enabled), the client hostname is present in the TLS handshake before any Kafka protocol bytes are exchanged. The gateway reads the SNI hostname and decides which backend service to forward the connection to. This means that one gateway address and one port can serve the bootstrap endpoint and every individual broker, distinguished purely by hostname. TLSRoute moved to the Standard API channel in Gateway API v1.4 and got a stable v1 API version in v1.5, making it a solid foundation to build on. How Strimzi uses TLSRoute When you configure a type: tlsroute listener, the Strimzi Cluster Operator takes care of all the Gateway API plumbing on your behalf: A bootstrap service pointing to all brokers is created, along with a bootstrap TLSRoute for the bootstrap hostname. A per-broker service and a per-broker TLSRoute are created for each Kafka broker node, using the per-broker hostname. You only need to: Deploy and configure a Gateway (using any Gateway API compatible controller). Reference that Gateway in your Kafka CR via the new parentRefs configuration field. Strimzi will create and keep the TLSRoute resources in sync. This is especially useful when you combine type: tlsroute with horizontal auto-scaling of broker node pools: as brokers are added or removed, Strimzi automatically creates or deletes the corresponding TLSRoute resources. TLS passthrough vs. TLS termination: the TLS mode is configured on the Gateway listener, not in Strimzi. With TLS passthrough, the encrypted connection travels all the way to the Kafka broker; the broker’s certificate is what clients verify. This is what we use in this guide and is the most common setup. TLS termination at the gateway is also possible in principle, but Gateway API controller support for it is still emerging. Trying it on minikube The rest of this post is a step-by-step walkthrough for running the type: tlsroute listener on a laptop using minikube and Envoy Gateway. At the end you will be able to produce and consume messages from outside the cluster using the standard Kafka client tools. We assume minikube is already running locally. If you need to set it up first, follow the minikube getting started guide. Prerequisites You will need the following tools installed: kubectl Helm 3 Strimzi 1.1.0+ installed in your cluster (the Quickstart is the fastest path) Kafka CLI tools (kafka-topics.sh, kafka-console-producer.sh, kafka-console-consumer.sh); alternatively, you can run them from inside a broker pod Step 1: Install Envoy Gateway Envoy Gateway ships with the Gateway API CRDs bundled, so there is no need to install them separately. helm install envoygateway oci://docker.io/envoyproxy/gateway-helm \ -n envoy-gateway-system --create-namespace kubectl wait --timeout=5m -n envoy-gateway-system \ deployment/envoy-gateway --for=condition=Available Verify the installation and confirm that the Gateway API CRDs are present: kubectl get pods -n envoy-gateway-system kubectl get crd | grep gateway You should see several CRDs including gateways.gateway.networking.k8s.io and tlsroutes.gateway.networking.k8s.io. Step 2: Create the EnvoyProxy resource The EnvoyProxy resource tells Envoy Gateway how to deploy the data-plane Envoy pods and what service type to use. On minikube we use LoadBalancer and rely on minikube tunnel to expose it. # envoy-proxy.yaml apiVersion: gateway.envoyproxy.io/v1alpha1 kind: EnvoyProxy metadata: name: minikube-proxy namespace: envoy-gateway-system spec: provider: type: Kubernetes kubernetes: envoyService: type: LoadBalancer kubectl apply -f envoy-proxy.yaml Step 3: Create the GatewayClass A GatewayClass is a cluster-scoped resource that registers a specific Gateway controller with Kubernetes, much like IngressClass does for Ingress controllers. Every Gateway you create later must reference a GatewayClass, which is how Kubernetes knows which controller should reconcile it. The controllerName field identifies the Envoy Gateway controller, and the parametersRef points to the EnvoyProxy resource we created in the previous step so that the controller knows how to deploy the data-plane pods. # gateway-class.yaml apiVersion: gateway.networking.k8s.io/v1 kind: GatewayClass metadata: name: envoy-gateway spec: controllerName: gateway.envoyproxy.io/gatewayclass-controller parametersRef: group: gateway.envoyproxy.io kind: EnvoyProxy name: minikube-proxy namespace: envoy-gateway-system kubectl apply -f gateway-class.yaml kubectl get gatewayclass The output should show the GatewayClass with ACCEPTED set to True, which means the Envoy Gateway controller has picked it up successfully. Step 4: Start minikube tunnel The LoadBalancer service created for the gateway needs an external IP. Open a new terminal and keep this command running throughout the session: minikube tunnel You may be prompted for your sudo password. Leave this terminal open and go back to your main terminal. Step 5: Create the Gateway A Gateway is an instance of a load balancer or proxy that listens for incoming traffic and routes it to backend services based on the attached route resources. It references a GatewayClass (via gatewayClassName) so Envoy Gateway knows it is responsible for reconciling this resource and deploying the corresponding Envoy proxy pods. The listener we define here is the entry point for all Kafka traffic: protocol: TLS with mode: Passthrough tells the gateway to forward the raw TLS connection directly to the backend without terminating it. The TLS handshake happens end-to-end between the Kafka client and the Kafka broker. port: 8443 is the port on which the gateway will accept connections from outside the cluster. hostname: "*.kafka.local" restricts this listener to SNI hostnames matching that wildcard, which covers both the bootstrap address and all per-broker addresses we will configure later. allowedRoutes.namespaces.from: All permits TLSRoute resources from any namespace to attach to this listener, which is needed because Strimzi will create the routes in the Kafka cluster’s namespace. # gateway.yaml apiVersion: gateway.networking.k8s.io/v1 kind: Gateway metadata: name: envoy-gateway namespace: envoy-gateway-system spec: gatewayClassName: envoy-gateway listeners: - name: tls-passthrough protocol: TLS port: 8443 hostname: "*.kafka.local" tls: mode: Passthrough allowedRoutes: namespaces: from: All kubectl apply -f gateway.yaml Wait a few seconds and then verify the Gateway is PROGRAMMED: kubectl get gateway envoy-gateway -n envoy-gateway-system If PROGRAMMED shows False, check that minikube tunnel is still running and that the LoadBalancer service has been assigned an EXTERNAL-IP: kubectl get svc -n envoy-gateway-system Step 6: Configure DNS Because we are running on a laptop, there is no real DNS server that can resolve the Kafka hostnames to the gateway’s address. We solve this by adding static entries to the local /etc/hosts file. This is the same technique used when doing local Kubernetes development: map the hostnames you care about directly to the IP exposed by minikube tunnel. The hostnames we need come from the Kafka listener configuration we will apply in Step 7. The bootstrap.host field sets the bootstrap address (bootstrap.kafka.local), and the hostTemplate field defines the per-broker naming pattern (broker-{nodeId}.kafka.local), which for a three-broker cluster produces broker-0.kafka.local, broker-1.kafka.local, and broker-2.kafka.local. We add all four entries now so that the cluster is reachable as soon as it finishes reconciling. First, retrieve the external IP that was assigned to the gateway: GATEWAY_IP=$(kubectl get gateway envoy-gateway -n envoy-gateway-system \ -o jsonpath='{.status.addresses[0].value}') echo $GATEWAY_IP Add entries to /etc/hosts so your laptop can resolve the Kafka hostnames: sudo tee -a /etc/hosts &lt;&lt;EOF ${GATEWAY_IP} bootstrap.kafka.local ${GATEWAY_IP} broker-0.kafka.local ${GATEWAY_IP} broker-1.kafka.local ${GATEWAY_IP} broker-2.kafka.local EOF You can verify that DNS resolves correctly with: ping -c 1 bootstrap.kafka.local Note that the ping itself will likely time out (the gateway only listens on TCP); what matters is that the hostname resolves to the right IP. Step 7: Deploy the Kafka cluster with a tlsroute listener We assume the Strimzi Cluster Operator is installed in the kafka namespace and we will deploy the Kafka cluster there as well. Create the Kafka and KafkaNodePool resources. The key part is the external listener of type: tlsroute, which instructs Strimzi to create TLSRoute resources instead of managing Ingress or LoadBalancer objects itself. A few fields in the listener configuration are worth calling out: parentRefs points to the Gateway resource created in Step 5. This is how Strimzi knows which gateway to attach the TLSRoute resources to. bootstrap.host sets the hostname advertised to Kafka clients for the initial connection. hostTemplate defines the per-broker hostname pattern. The {nodeId} placeholder is replaced by the actual broker node ID at runtime. advertisedPortTemplate: 8443 fixes the advertised port to 8443 for every broker, matching the single port our gateway listener is configured on. # kafka-cluster.yaml apiVersion: kafka.strimzi.io/v1 kind: KafkaNodePool metadata: name: controller labels: strimzi.io/cluster: my-cluster spec: replicas: 3 roles: - controller storage: type: jbod volumes: - id: 0 type: ephemeral kraftMetadata: shared --- apiVersion: kafka.strimzi.io/v1 kind: KafkaNodePool metadata: name: broker labels: strimzi.io/cluster: my-cluster spec: replicas: 3 roles: - broker storage: type: jbod volumes: - id: 0 type: ephemeral kraftMetadata: shared --- apiVersion: kafka.strimzi.io/v1 kind: Kafka metadata: name: my-cluster spec: kafka: version: 4.3.0 metadataVersion: 4.3-IV0 listeners: - name: plain port: 9092 type: internal tls: false - name: tls port: 9093 type: internal tls: true - name: external port: 9094 type: tlsroute tls: true configuration: bootstrap: host: bootstrap.kafka.local parentRefs: - kind: Gateway group: gateway.networking.k8s.io name: envoy-gateway namespace: envoy-gateway-system hostTemplate: broker-{nodeId}.kafka.local advertisedPortTemplate: "8443" config: offsets.topic.replication.factor: 3 transaction.state.log.replication.factor: 3 transaction.state.log.min.isr: 2 default.replication.factor: 3 min.insync.replicas: 2 entityOperator: topicOperator: {} userOperator: {} kubectl apply -f kafka-cluster.yaml -n kafka kubectl wait kafka/my-cluster -n kafka --for=condition=Ready --timeout=300s Once the cluster is ready, verify that Strimzi has created the TLSRoute resources automatically in the kafka namespace: kubectl get tlsroute -n kafka You should see one bootstrap route and one route per broker: NAME HOSTNAMES AGE my-cluster-kafka-bootstrap ["bootstrap.kafka.local"] 2m my-cluster-broker-0 ["broker-0.kafka.local"] 2m my-cluster-broker-1 ["broker-1.kafka.local"] 2m my-cluster-broker-2 ["broker-2.kafka.local"] 2m Tip: If the TLSRoute resources are not created and the Cluster Operator logs show The Gateway API TLSRoute resource is not available in this Kubernetes cluster, the operator was started before the Gateway API CRDs were installed. Simply restart it (replace &lt;operator-namespace&gt; with the namespace where Strimzi is installed, e.g. strimzi if you used the Quickstart): kubectl rollout restart deployment strimzi-cluster-operator -n &lt;operator-namespace&gt; Step 8: Test the connection Before connecting Kafka clients, we need to extract the cluster CA certificate that Strimzi generated for the cluster. Clients must trust this CA to be able to establish a TLS connection to the brokers. kubectl get secret my-cluster-cluster-ca-cert -n kafka \ -o jsonpath='{.data.ca\.crt}' | base64 -d &gt; ca.crt With the CA certificate in hand, do a quick sanity check with OpenSSL to verify the TLS passthrough is working end to end: openssl s_client -connect broker-0.kafka.local:8443 \ -servername broker-0.kafka.local -showcerts You should see CONNECTED and the broker certificate chain. A Verify return code: 19 (self-signed certificate in certificate chain) is expected; the important thing is that the TLS handshake completes successfully. Now test with the Kafka CLI tools. All commands need to know the bootstrap address and that TLS is required, so start by creating a client properties file that every tool will share via --command-config or --producer.config / --consumer.config: # client-ssl.properties bootstrap.servers=bootstrap.kafka.local:8443 security.protocol=SSL ssl.truststore.type=PEM ssl.truststore.location=ca.crt The ssl.truststore.location points to the ca.crt file we just extracted. Using ssl.truststore.type=PEM means we can pass the certificate file directly without converting it to a Java keystore first. First, verify that the client can reach the cluster and list topics. At this point the list will be empty, but a successful response confirms that the bootstrap connection and broker metadata exchange are working correctly: kafka-topics.sh --bootstrap-server bootstrap.kafka.local:8443 \ --command-config client-ssl.properties \ --list Next, create a test topic with three partitions and a replication factor of three, one replica per broker: kafka-topics.sh --bootstrap-server bootstrap.kafka.local:8443 \ --command-config client-ssl.properties \ --create --topic test-topic \ --partitions 3 --replication-factor 3 With the topic in place, open an interactive producer session and type a few messages, pressing Enter after each one. Press Ctrl+C when you are done to close the producer: kafka-console-producer.sh --bootstrap-server bootstrap.kafka.local:8443 \ --producer.config client-ssl.properties \ --topic test-topic Finally, start a consumer reading from the beginning of the topic. It should print every message you just produced, which confirms that the per-broker TLSRoute resources are working correctly. Each message was written to a specific broker and the consumer was able to reach that broker individually through its own dedicated route: kafka-console-consumer.sh --bootstrap-server bootstrap.kafka.local:8443 \ --consumer.config client-ssl.properties \ --topic test-topic \ --from-beginning Press Ctrl+C to stop the consumer once you have seen all the messages. Conclusion The new type: tlsroute listener brings first-class Gateway API support to Strimzi. It fills the gap left by the deprecated type: ingress listener and does so on a stable, vendor-neutral standard that has broad ecosystem support. From a user perspective, the configuration is straightforward: bring your own Gateway, point Strimzi at it via parentRefs, and Strimzi takes care of creating and maintaining the TLSRoute resources, including as brokers are scaled up or down. From a protocol perspective, TLS-SNI-based routing gives you the clean one-address-one-port topology that is so important for the Kafka protocol, without the complexity of managing one unique IP per broker that TCPRoute would require. If you are currently using type: ingress and wondering what to migrate to, type: tlsroute is the answer. Any Gateway API compatible controller will work; in this post we used Envoy Gateway, but you could equally use Cilium Gateway API, Istio, NGINX Gateway Fabric, or any other implementation you already have in your cluster. For more background on the design decisions behind this feature, have a look at Strimzi proposal #136.]]></summary></entry><entry><title type="html">Meet Strimzi’s New AI Assistant: Kapa.ai</title><link href="https://strimzi.io/blog/2026/07/07/kapa-ai-assistant/" rel="alternate" type="text/html" title="Meet Strimzi’s New AI Assistant: Kapa.ai" /><published>2026-07-07T00:00:00+00:00</published><updated>2026-07-07T00:00:00+00:00</updated><id>https://strimzi.io/blog/2026/07/07/kapa-ai-assistant</id><content type="html" xml:base="https://strimzi.io/blog/2026/07/07/kapa-ai-assistant/"><![CDATA[<p>If you have visited the <a href="https://strimzi.io">Strimzi website</a> recently, you may have noticed something new: a small floating button in the bottom-right corner of every page.
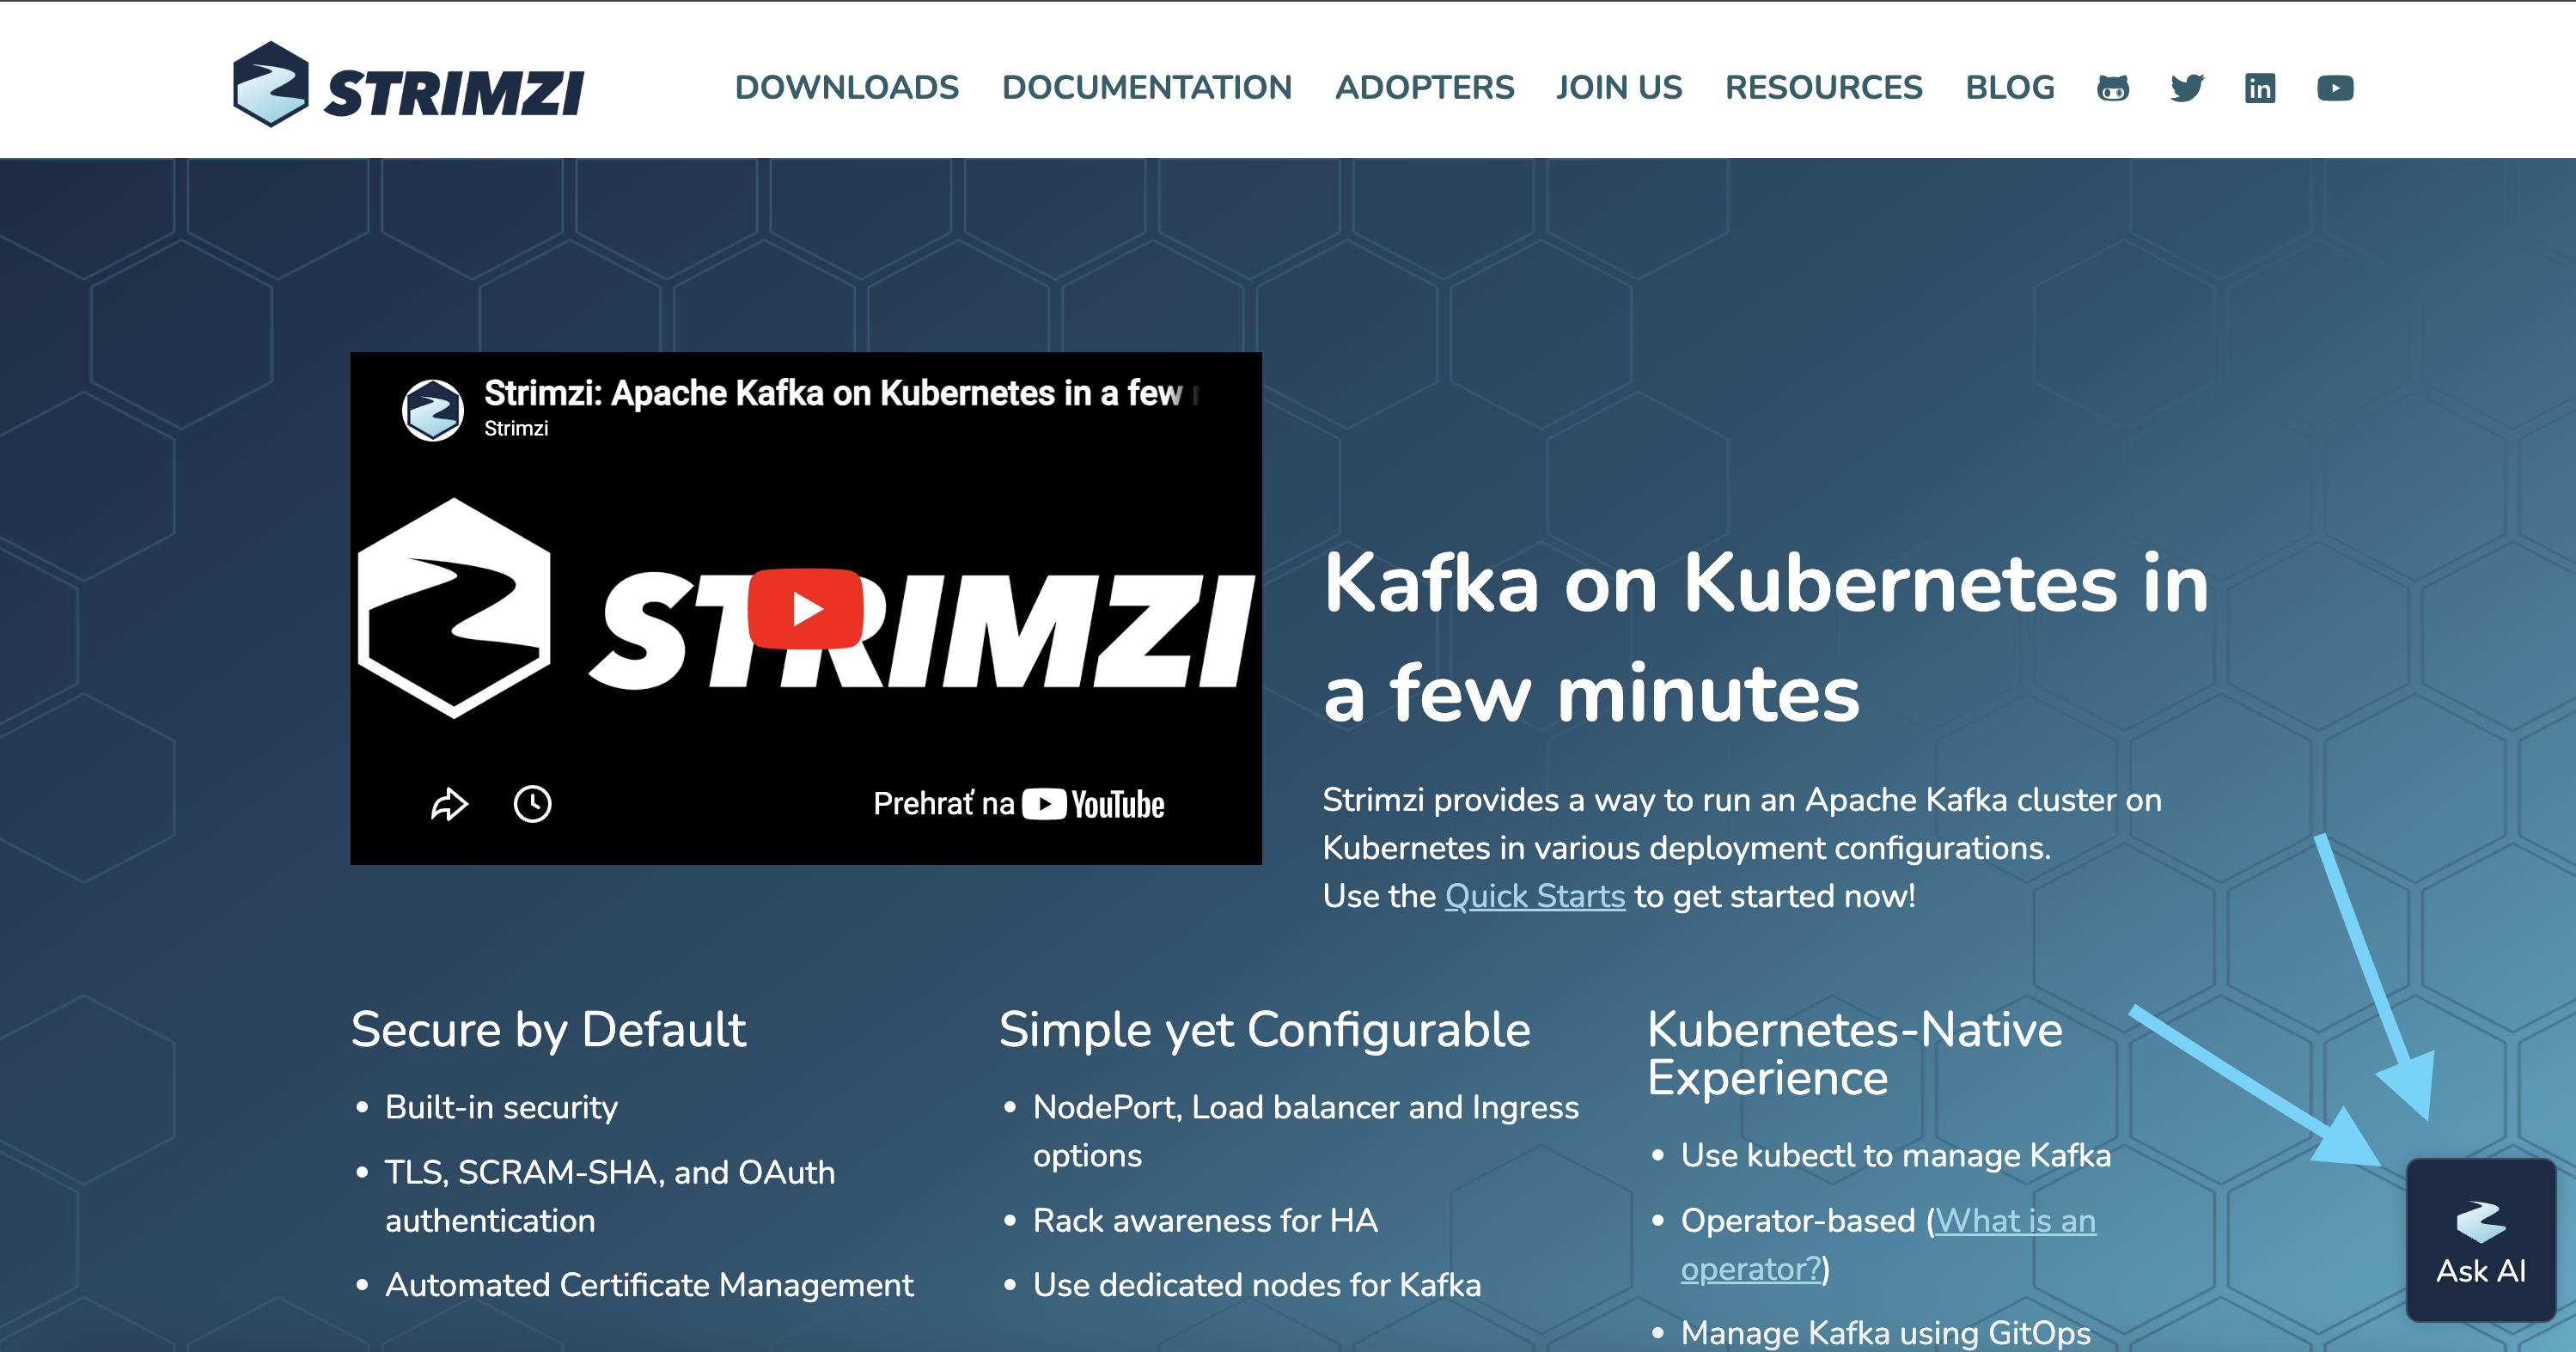
That is <a href="https://www.kapa.ai/">Kapa.ai</a>, an AI-powered assistant now available across the entire Strimzi website, ready to help you find answers to your questions about Strimzi and Apache Kafka on Kubernetes.</p>

<!--more-->

<p><img src="/assets/images/posts/2026-07-07-kapa-ai-widget.png" alt="Kapa.ai widget on the Strimzi website" /></p>

<h3 id="why-we-added-an-ai-assistant">Why We Added an AI Assistant</h3>

<p>As Strimzi has grown, so has the volume of questions from the community.
Many of these questions, whether they come through <a href="https://slack.cncf.io/">Slack</a>, <a href="https://github.com/strimzi/strimzi-kafka-operator/discussions">GitHub Discussions</a>, or issues, are already answered somewhere in our documentation.
But finding the right answer in the right place is not always easy, especially for newcomers.</p>

<p>Maintainers spend a significant amount of time answering repetitive questions, which takes time away from development, reviews, and other project work.
This is a common challenge across open-source projects, sometimes called the “support tax.”</p>

<p>The <a href="https://contribute.cncf.io/blog/2026/04/09/reducing-support-tax-cncf-kapa-ai/">CNCF partnered with Kapa.ai</a> to offer AI-powered assistants to all CNCF projects, free of charge.
When we saw the opportunity, we decided to try it out for Strimzi.</p>

<h3 id="what-is-kapaai">What Is Kapa.ai?</h3>

<p>Kapa.ai is an AI assistant platform built specifically for technical communities.
Unlike a general-purpose chatbot, it uses Retrieval Augmented Generation (RAG) to ground its responses in a project’s actual knowledge base.
This means answers come from Strimzi’s own documentation, GitHub issues, discussions, and other project-specific sources, rather than from a generic language model that might hallucinate.</p>

<h3 id="how-it-works">How It Works</h3>

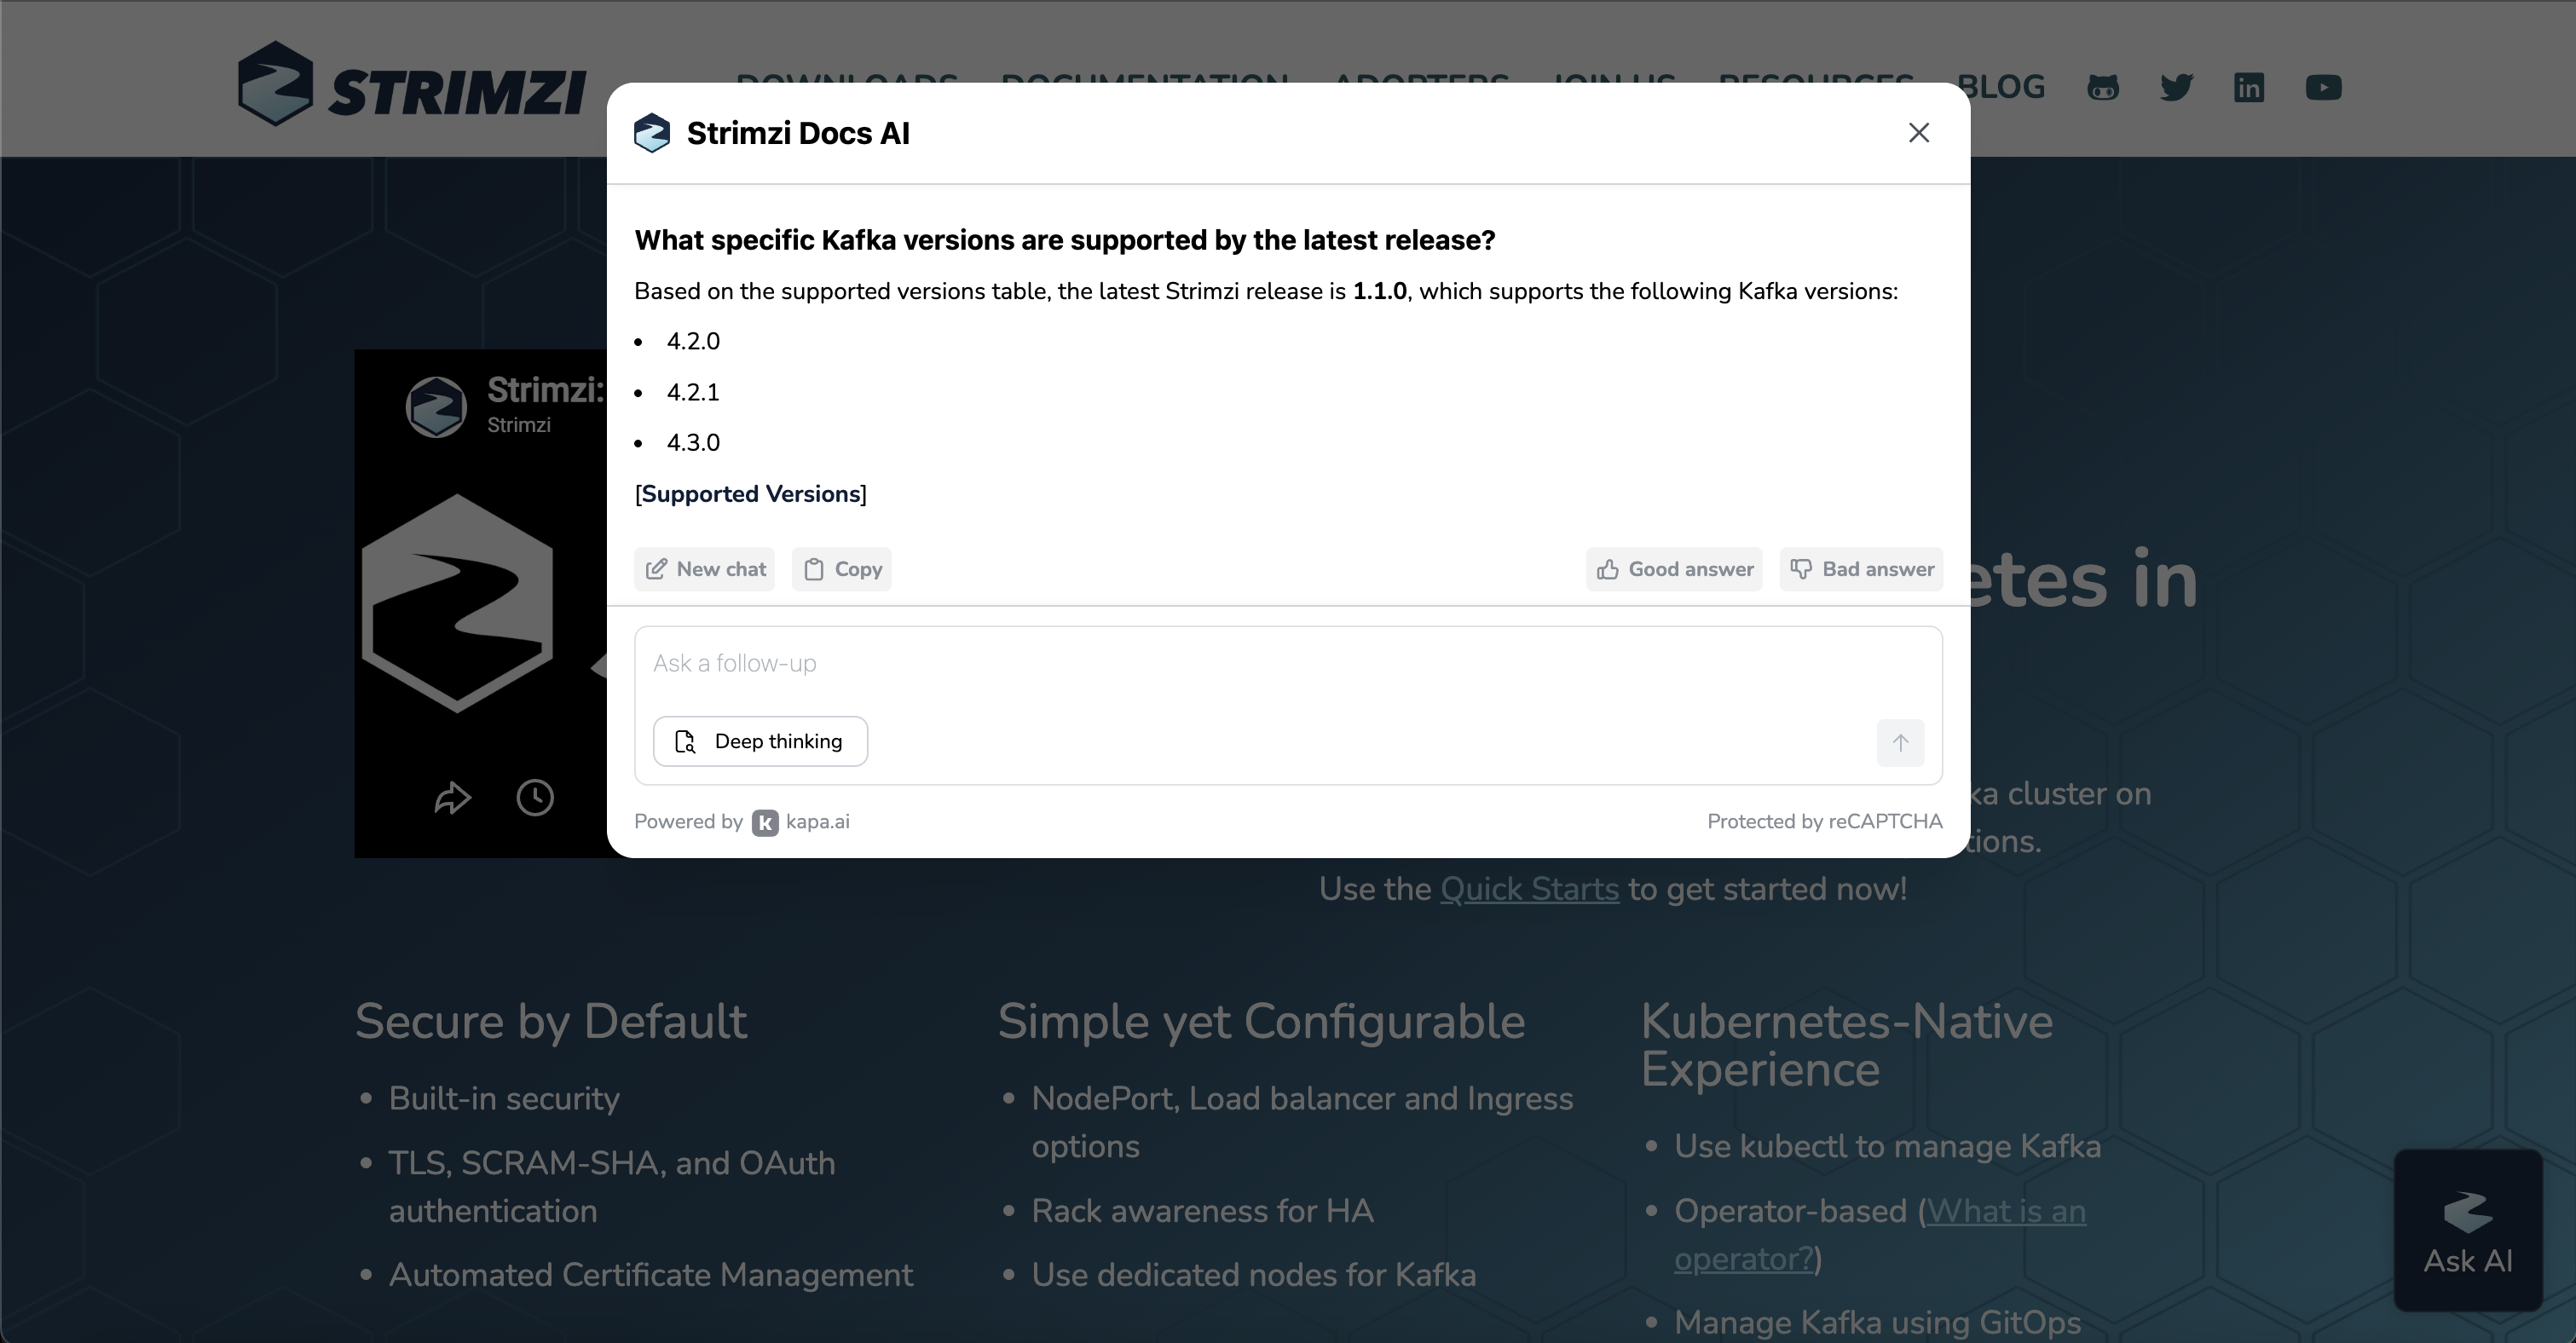
<p>Click the Strimzi icon in the bottom-right corner of any page on the Strimzi website, and a chat window opens.
You can ask questions in natural language, and Kapa.ai will search through the Strimzi knowledge base to find relevant answers.</p>

<p><img src="/assets/images/posts/2026-07-07-kapa-ai-chat.png" alt="Kapa.ai chat window" /></p>

<p>Each answer includes references to the source material, so you can verify the information and dive deeper if needed.</p>

<p>Here are a few examples of questions you could ask:</p>
<ul>
  <li>“How do I configure TLS for Kafka listeners in Strimzi?”</li>
  <li>“What is the difference between KRaft and ZooKeeper mode in Strimzi?”</li>
  <li>“How do I set up Kafka Connect with Strimzi?”</li>
  <li>“What annotations control certificate renewal?”</li>
</ul>

<h3 id="what-kapaai-means-for-the-community">What Kapa.ai Means for the Community</h3>

<p>The goal is not to replace human interaction.
Strimzi’s community channels remain the best place for in-depth discussions, design conversations, and collaboration.</p>

<p>What Kapa.ai does is handle the common, well-documented questions, so maintainers can focus on the work that needs a human: code reviews, design decisions, mentoring contributors, and pushing the project forward.</p>

<p>It also helps identify gaps in our documentation.
When the assistant cannot answer a question, that is a signal that we may need to improve our docs in that area.</p>

<h3 id="privacy-and-data">Privacy and Data</h3>

<p>Kapa.ai does <strong>not</strong> use community question-and-answer data for training models or any other purpose.
Your data stays with the project.
You can read more about the CNCF’s partnership and data policies in their <a href="https://contribute.cncf.io/blog/2026/04/09/reducing-support-tax-cncf-kapa-ai/">announcement blog post</a>.</p>

<h3 id="try-it-out">Try It Out</h3>

<p>Head over to <a href="https://strimzi.io">strimzi.io</a> and click the floating Strimzi icon in the bottom-right corner.
Ask it anything about Strimzi, and let us know what you think.</p>

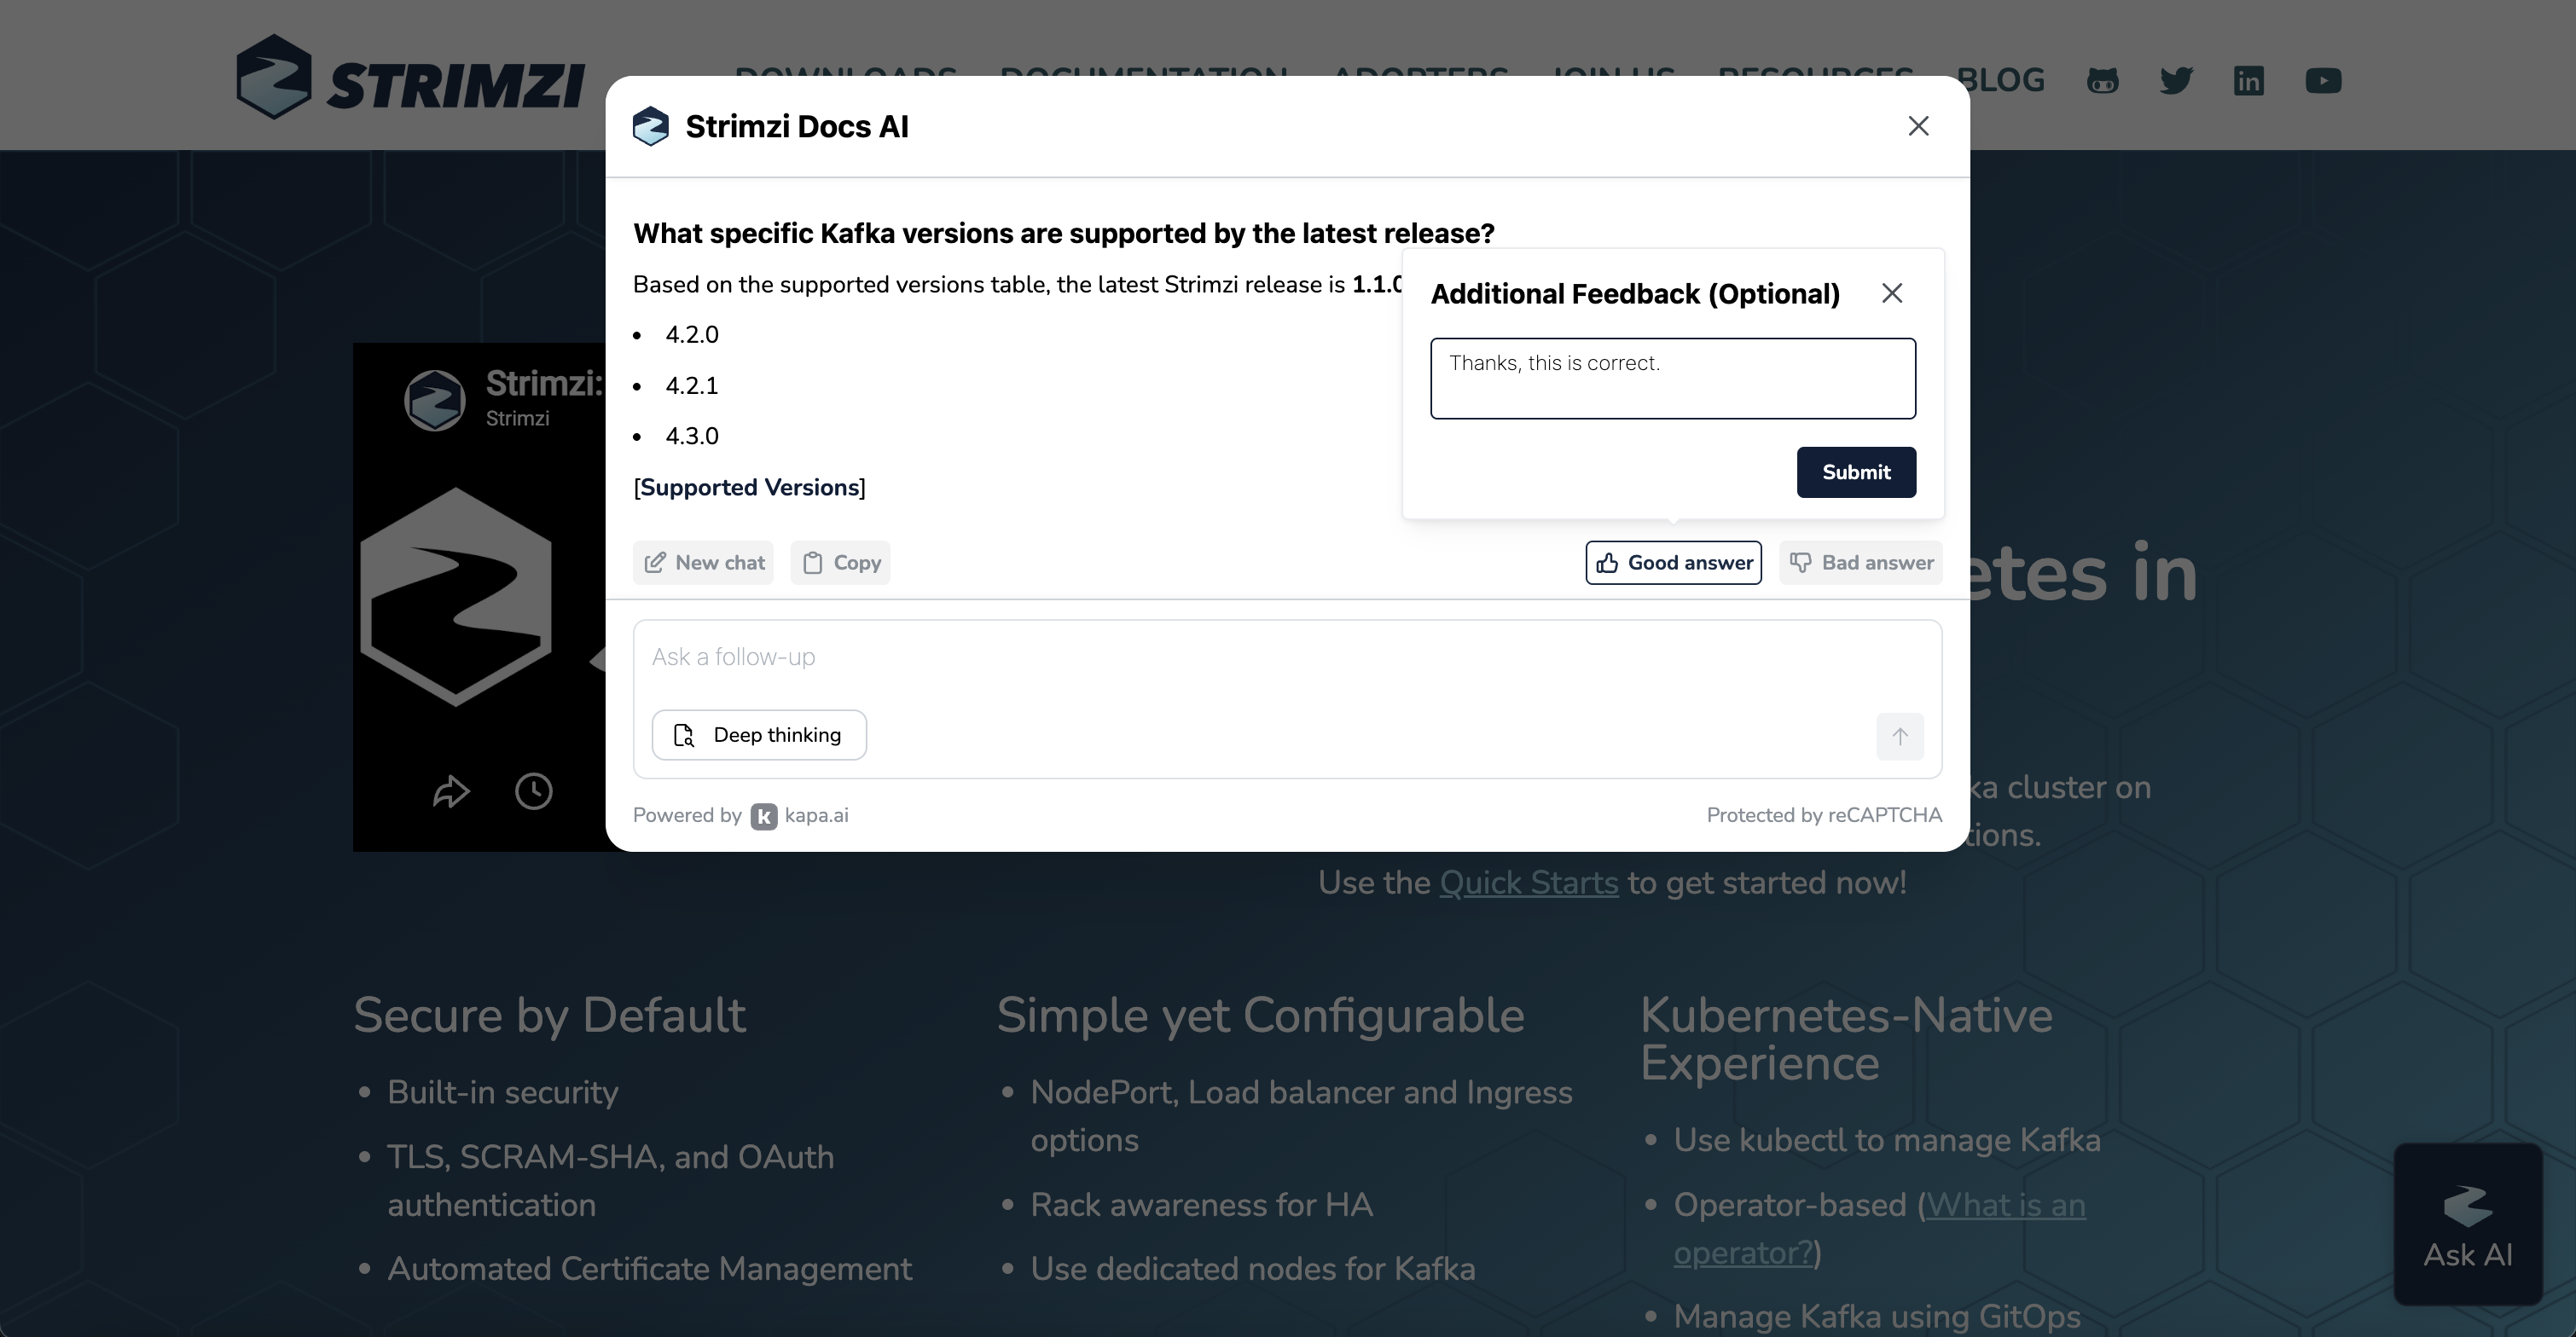
<p>After each answer, you will see “Good Answer” and “Bad Answer” buttons along with an optional text field where you can explain your rating.</p>

<p><img src="/assets/images/posts/2026-07-07-kapa-ai-chat-feedback.png" alt="Kapa.ai feedback buttons" /></p>

<p>This feedback loop matters. 
Positive ratings confirm that the knowledge base is working well, while negative ratings with a short rationale help us pinpoint where the assistant falls short and where our documentation needs improvement.</p>

<p>We would love to hear your experience.
Share your feedback on the <a href="https://cloud-native.slack.com/channels/strimzi">#strimzi</a> Slack channel or open a <a href="https://github.com/strimzi/strimzi-kafka-operator/discussions">GitHub Discussion</a>.</p>]]></content><author><name>Maros Orsak</name></author><summary type="html"><![CDATA[If you have visited the Strimzi website recently, you may have noticed something new: a small floating button in the bottom-right corner of every page. That is Kapa.ai, an AI-powered assistant now available across the entire Strimzi website, ready to help you find answers to your questions about Strimzi and Apache Kafka on Kubernetes.]]></summary></entry><entry><title type="html">Video: What’s new in Strimzi 1.1.0</title><link href="https://strimzi.io/blog/2026/06/27/what-is-new-in-strimzi-1.1.0/" rel="alternate" type="text/html" title="Video: What’s new in Strimzi 1.1.0" /><published>2026-06-27T00:00:00+00:00</published><updated>2026-06-27T00:00:00+00:00</updated><id>https://strimzi.io/blog/2026/06/27/what-is-new-in-strimzi-1.1.0</id><content type="html" xml:base="https://strimzi.io/blog/2026/06/27/what-is-new-in-strimzi-1.1.0/"><![CDATA[<p>Strimzi 1.1.0 has been released with multiple new features and improvements.
As with previous releases, we created a video that introduces the main changes.
You can watch the video here or on our <a href="https://youtu.be/NNnKKfx2Yuk">YouTube channel</a> and check the <a href="https://github.com/strimzi/strimzi-kafka-operator/releases/tag/1.1.0">release notes</a>.</p>

<!--more-->

<iframe width="560" height="315" src="https://www.youtube.com/embed/NNnKKfx2Yuk" frameborder="0" allow="accelerometer; autoplay; encrypted-media; gyroscope; picture-in-picture" allowfullscreen=""></iframe>]]></content><author><name>Lukas Kral</name></author><summary type="html"><![CDATA[Strimzi 1.1.0 has been released with multiple new features and improvements. As with previous releases, we created a video that introduces the main changes. You can watch the video here or on our YouTube channel and check the release notes.]]></summary></entry><entry><title type="html">Replaying the Stream: StrimziCon 2026 Recap and Recordings</title><link href="https://strimzi.io/blog/2026/06/23/strimzicon2026-roundup/" rel="alternate" type="text/html" title="Replaying the Stream: StrimziCon 2026 Recap and Recordings" /><published>2026-06-23T00:00:00+00:00</published><updated>2026-06-23T00:00:00+00:00</updated><id>https://strimzi.io/blog/2026/06/23/strimzicon2026-roundup</id><content type="html" xml:base="https://strimzi.io/blog/2026/06/23/strimzicon2026-roundup/"><![CDATA[<p><img src="/assets/images/posts/2026-02-18-strimzicon2026-banner.png" alt="StrimziCon 2026 Banner" /></p>

<p>StrimziCon is over for another year!</p>

<p>The 2026 program included:</p>
<ul>
  <li>6 sessions</li>
  <li>10 speakers from 5 organizations</li>
  <li>Over 4 hours of content</li>
</ul>

<p>This year’s content included tips for running in production, best practices for using Strimzi components, and real-world use cases shared by maintainers, contributors and users of Strimzi.
In the breaks between sessions attendees connected and shared their own experiences with Strimzi.</p>

<p>A massive thank you to everyone who joined us live on the day, our wonderful speakers, the program committee who built the schedule, and to <a href="https://www.cncf.io/">CNCF</a> for hosting the event.</p>

<h3 id="session-recordings-and-slides">Session Recordings and Slides</h3>

<p>All the session recordings are now available on the <a href="https://www.youtube.com/watch?v=8U7jBzDJd8c&amp;list=PLpI4X8PMthYcTXj9tpcLEpTgEBxQrZyBc">Strimzi YouTube channel</a>.
To help you choose which one to watch first, here’s an introduction to each session, as well as links to the recording and slides.</p>

<h5 id="keynote-recordingslides">Keynote (<a href="https://youtu.be/8U7jBzDJd8c?si=OaSNrwdDSc78bph2">Recording</a>/<a href="https://docs.google.com/presentation/d/1zOAeyVpBJdCTJOcfwch6nv4Ag-gF4UlnBUCo8It1_H8/edit?usp=sharing">Slides</a>)</h5>

<p><em>Speakers: Paolo Patierno &amp; Kate Stanley @ IBM</em></p>

<p>Paolo and Kate opened the event by sharing the latest features and improvements that have been added to Strimzi over the past year, including the long awaited 1.0.0 release. They also shared some insights into how the 1.0.0 release came about and provided a glimpse into what’s on the horizon for the project.
Finally, they shared some updates from the community, including new ways to keep up with the wider community, the new AI policy and the path to graduation.</p>

<h5 id="beyond-the-install-take-full-ownership-of-your-strimzi-cluster-recordingslides">Beyond the Install: Take full ownership of your Strimzi cluster (<a href="https://youtu.be/0MOxDjfqQuM?si=pd7akJBHE7RIX41m">Recording</a>/<a href="https://drive.google.com/file/d/1PaDxgG_RzkmeDzBb_tNyMVu4QJpJB9vF/view?usp=sharing">Slides</a>)</h5>

<p><em>Speaker: Jakub Scholz @ Cloudera</em></p>

<p>Jakub challenged the notion that open source is “free” and explored what it really means to own your Strimzi installation in production.
The session covered critical aspects of Strimzi ownership including securing your container supply chain, mirroring images, and handling CVEs in base images and dependencies even when there’s no official patch release.</p>

<h5 id="who-are-you-configuring-kafka-authentication-in-strimzi-from-tls-to-custom-principals-recordingslides">Who Are You? Configuring Kafka Authentication in Strimzi from TLS to Custom Principals (<a href="https://youtu.be/zuFNBBsYyZg?si=VngmyYvpFey-a6ex">Recording</a>/<a href="https://drive.google.com/file/d/18k5uHRrHn9PhZkkcQ1Jos7xm8PriUA7O/view?usp=sharing">Slides</a>)</h5>

<p><em>Speaker: Daniel Mulder @ Axual</em></p>

<p>Daniel walked through the full range of authentication options available in Strimzi, from basic TLS authentication to advanced custom principal builders.
The session explored listener-aware authentication patterns and how to implement a robust multi-tenancy strategy, while also discussing the risks of leaning too heavily on Strimzi internals and how to add authorization into the picture.</p>

<h5 id="swapping-the-engine-mid-flight-how-we-moved-reddits-petabyte-scale-kafka-fleet-to-kubernetes-recordingslides">Swapping the Engine Mid-Flight: How We Moved Reddit’s Petabyte Scale Kafka Fleet to Kubernetes (<a href="https://youtu.be/6XIAgk8Hn5I?si=GxqhPjMSyc4f62_u">Recording</a>/<a href="https://drive.google.com/file/d/1A72401dsS7dpqx7qx9gD_nXoW-_5RWaC/view?usp=sharing">Slides</a>)</h5>

<p><em>Speaker: Sky Kistler @ Reddit</em></p>

<p>Sky shared Reddit’s remarkable journey of migrating 500+ EC2-backed Kafka brokers and petabytes of data to Strimzi on Kubernetes with zero downtime.
The session detailed their innovative “stretch cluster” approach, including DNS facade implementation, hybrid cluster setup by temporarily forking the Strimzi operator, and the step-by-step process that treated the migration as a series of safe, reversible operations rather than a risky “lift and shift.”</p>

<h5 id="building-strimzi-mcp-server-for-kubernetes-democratizing-platform-expertise-through-llms-recordingslides">Building Strimzi MCP Server for Kubernetes: Democratizing Platform Expertise Through LLMs (<a href="https://youtu.be/D-9Bd8ps7p8?si=wMpgdnjL4sK0uqKR">Recording</a>/<a href="https://drive.google.com/file/d/1rkPHU3zcNMpRtrj2Az1QL0FBldiKIihw/view?usp=sharing">Slides</a>)</h5>

<p><em>Speaker: David Kornel, Jakub Stejskal @ IBM</em></p>

<p>David and Jakub demonstrated how they built an open-source MCP server for Strimzi that makes platform expertise accessible through natural language interactions with LLMs.
The session included a live demo of incident diagnosis, explained the implementation using Quarkus, and discussed how structured data and prompt templates guide the LLM through expert-level troubleshooting steps while catching misconfigurations without requiring extensive documentation reading.</p>

<h5 id="from-running-to-operating-real-world-strimzi-in-production-recordingslides">From Running to Operating: Real-World Strimzi in Production (<a href="https://youtu.be/lwL7ghlSU6s?si=T_W6B6u7StMwHWDH">Recording</a>/<a href="https://drive.google.com/file/d/15wt5t8gr4VioHU7Zu5iTlAPHDF3vNJBE/view?usp=sharing">Slides</a>)</h5>

<p><em>Speakers: Rajith Attapattu @ Randoli</em></p>

<p>Rajith shared a real-world case study of running Strimzi at scale, covering architecture choices, monitoring insights and how they handled the upgrade to Strimzi 1.0.0.
The session explored how to instrument Strimzi with OpenTelemetry, identify signals that actually matter, and build actionable observability, along with operational patterns that help teams move from reactive firefighting to proactive reliability.</p>

<h5 id="disaster-recovery-in-action-with-kafka-and-strimzi-recordingslides">Disaster Recovery in action with Kafka and Strimzi (<a href="https://youtu.be/FdGm5o_74cw?si=72mpoe_w0Vy5hs-V">Recording</a>/<a href="https://drive.google.com/file/d/1PpsD1HjYRUoved0TnD39utAbaiXBW3ci/view?usp=sharing">Slides</a>)</h5>

<p><em>Speaker: Mickael Maison, Gantigmaa Selenge @ IBM</em></p>

<p>Mickael and Tina walked through the key considerations for setting up and operating a disaster recovery environment for Kafka using Strimzi and MirrorMaker.
The session covered monitoring replication lag and health, clean and unclean failover/failback procedures, offset translation semantics, and important limitations and pitfalls to be aware of when implementing disaster recovery.</p>

<h5 id="closing-recordingslides">Closing (<a href="https://youtu.be/Mh-Ac4grti0?si=kA9sOZgJf_FxE9wJ">Recording</a>/<a href="https://docs.google.com/presentation/d/1zOAeyVpBJdCTJOcfwch6nv4Ag-gF4UlnBUCo8It1_H8/edit?usp=sharing">Slides</a>)</h5>

<p><em>Speakers: Paolo Patierno &amp; Kate Stanley @ IBM</em></p>

<p>Paolo and Kate closed the event by reflecting on the day’s sessions and thanking the speakers, attendees, and everyone who contributed to making StrimziCon 2026 a success.
They also posed some final questions to the audience and shared some insights from Strimzi maintainers on their favourite features and what they are looking forward to coming to the project in future.</p>

<h3 id="what-next">What Next?</h3>

<p>If you’ve run out of StrimziCon 2026 sessions to watch, why not check out our <a href="https://youtube.com/playlist?list=PLpI4X8PMthYd-rxC90Her68tgRhIFbTAQ&amp;feature=shared">playlist</a> of last year’s event.
Find out how you can help the Strimzi community on our <a href="https://strimzi.io/join-us/">Join Us</a> page on the website.</p>

<p>Thanks again to everyone who made this year’s event such a success.</p>]]></content><author><name>Paolo Patierno</name></author><summary type="html"><![CDATA[StrimziCon is over for another year! The 2026 program included: 6 sessions 10 speakers from 5 organizations Over 4 hours of content This year’s content included tips for running in production, best practices for using Strimzi components, and real-world use cases shared by maintainers, contributors and users of Strimzi. In the breaks between sessions attendees connected and shared their own experiences with Strimzi. A massive thank you to everyone who joined us live on the day, our wonderful speakers, the program committee who built the schedule, and to CNCF for hosting the event. Session Recordings and Slides All the session recordings are now available on the Strimzi YouTube channel. To help you choose which one to watch first, here’s an introduction to each session, as well as links to the recording and slides. Keynote (Recording/Slides) Speakers: Paolo Patierno &amp; Kate Stanley @ IBM Paolo and Kate opened the event by sharing the latest features and improvements that have been added to Strimzi over the past year, including the long awaited 1.0.0 release. They also shared some insights into how the 1.0.0 release came about and provided a glimpse into what’s on the horizon for the project. Finally, they shared some updates from the community, including new ways to keep up with the wider community, the new AI policy and the path to graduation. Beyond the Install: Take full ownership of your Strimzi cluster (Recording/Slides) Speaker: Jakub Scholz @ Cloudera Jakub challenged the notion that open source is “free” and explored what it really means to own your Strimzi installation in production. The session covered critical aspects of Strimzi ownership including securing your container supply chain, mirroring images, and handling CVEs in base images and dependencies even when there’s no official patch release. Who Are You? Configuring Kafka Authentication in Strimzi from TLS to Custom Principals (Recording/Slides) Speaker: Daniel Mulder @ Axual Daniel walked through the full range of authentication options available in Strimzi, from basic TLS authentication to advanced custom principal builders. The session explored listener-aware authentication patterns and how to implement a robust multi-tenancy strategy, while also discussing the risks of leaning too heavily on Strimzi internals and how to add authorization into the picture. Swapping the Engine Mid-Flight: How We Moved Reddit’s Petabyte Scale Kafka Fleet to Kubernetes (Recording/Slides) Speaker: Sky Kistler @ Reddit Sky shared Reddit’s remarkable journey of migrating 500+ EC2-backed Kafka brokers and petabytes of data to Strimzi on Kubernetes with zero downtime. The session detailed their innovative “stretch cluster” approach, including DNS facade implementation, hybrid cluster setup by temporarily forking the Strimzi operator, and the step-by-step process that treated the migration as a series of safe, reversible operations rather than a risky “lift and shift.” Building Strimzi MCP Server for Kubernetes: Democratizing Platform Expertise Through LLMs (Recording/Slides) Speaker: David Kornel, Jakub Stejskal @ IBM David and Jakub demonstrated how they built an open-source MCP server for Strimzi that makes platform expertise accessible through natural language interactions with LLMs. The session included a live demo of incident diagnosis, explained the implementation using Quarkus, and discussed how structured data and prompt templates guide the LLM through expert-level troubleshooting steps while catching misconfigurations without requiring extensive documentation reading. From Running to Operating: Real-World Strimzi in Production (Recording/Slides) Speakers: Rajith Attapattu @ Randoli Rajith shared a real-world case study of running Strimzi at scale, covering architecture choices, monitoring insights and how they handled the upgrade to Strimzi 1.0.0. The session explored how to instrument Strimzi with OpenTelemetry, identify signals that actually matter, and build actionable observability, along with operational patterns that help teams move from reactive firefighting to proactive reliability. Disaster Recovery in action with Kafka and Strimzi (Recording/Slides) Speaker: Mickael Maison, Gantigmaa Selenge @ IBM Mickael and Tina walked through the key considerations for setting up and operating a disaster recovery environment for Kafka using Strimzi and MirrorMaker. The session covered monitoring replication lag and health, clean and unclean failover/failback procedures, offset translation semantics, and important limitations and pitfalls to be aware of when implementing disaster recovery. Closing (Recording/Slides) Speakers: Paolo Patierno &amp; Kate Stanley @ IBM Paolo and Kate closed the event by reflecting on the day’s sessions and thanking the speakers, attendees, and everyone who contributed to making StrimziCon 2026 a success. They also posed some final questions to the audience and shared some insights from Strimzi maintainers on their favourite features and what they are looking forward to coming to the project in future. What Next? If you’ve run out of StrimziCon 2026 sessions to watch, why not check out our playlist of last year’s event. Find out how you can help the Strimzi community on our Join Us page on the website. Thanks again to everyone who made this year’s event such a success.]]></summary></entry><entry><title type="html">Video: What’s new in Strimzi 1.0.0</title><link href="https://strimzi.io/blog/2026/04/28/what-is-new-in-strimzi-1.0.0/" rel="alternate" type="text/html" title="Video: What’s new in Strimzi 1.0.0" /><published>2026-04-28T00:00:00+00:00</published><updated>2026-04-28T00:00:00+00:00</updated><id>https://strimzi.io/blog/2026/04/28/what-is-new-in-strimzi-1.0.0</id><content type="html" xml:base="https://strimzi.io/blog/2026/04/28/what-is-new-in-strimzi-1.0.0/"><![CDATA[<p>Strimzi 1.0.0 has been released with multiple new features and improvements.
As with previous releases, we created a video that introduces the main changes.
You can watch the video here or on our <a href="https://youtu.be/-Zp9azOgFfQ">YouTube channel</a> and check the <a href="https://github.com/strimzi/strimzi-kafka-operator/releases/tag/1.0.0">release notes</a>.</p>

<!--more-->

<iframe width="560" height="315" src="https://www.youtube.com/embed/-Zp9azOgFfQ" frameborder="0" allow="accelerometer; autoplay; encrypted-media; gyroscope; picture-in-picture" allowfullscreen=""></iframe>]]></content><author><name>Jakub Scholz</name></author><summary type="html"><![CDATA[Strimzi 1.0.0 has been released with multiple new features and improvements. As with previous releases, we created a video that introduces the main changes. You can watch the video here or on our YouTube channel and check the release notes.]]></summary></entry><entry><title type="html">StrimziCon 2026: Schedule announced!</title><link href="https://strimzi.io/blog/2026/04/17/strimzicon2026-schedule/" rel="alternate" type="text/html" title="StrimziCon 2026: Schedule announced!" /><published>2026-04-17T00:00:00+00:00</published><updated>2026-04-17T00:00:00+00:00</updated><id>https://strimzi.io/blog/2026/04/17/strimzicon2026-schedule</id><content type="html" xml:base="https://strimzi.io/blog/2026/04/17/strimzicon2026-schedule/"><![CDATA[<p>We are very pleased to announce the speakers and sessions for the third edition of StrimziCon!
The interest from the community was really high and we received a lot of awesome proposals.
The program committee found it really tough to choose among them in order to build an amazing agenda.</p>

<!--more-->

<p><img src="/assets/images/posts/2026-02-18-strimzicon2026-banner.png" alt="StrimziCon 2026 Banner" /></p>

<h3 id="awesome-sessions--join-strimzicon">Awesome sessions … join StrimziCon!</h3>

<p>The conference will take place on <strong>Wednesday, June 3rd, 2026</strong> (afternoon CEST).
The event opens with a keynote from Kate Stanley and Paolo Patierno (IBM, Strimzi maintainers).
The keynote is followed by almost 4 hours of breakout sessions with topics covering core Strimzi features, use cases, operations, and integrations.</p>

<table>
  <thead>
    <tr>
      <th style="text-align: center">Time (CEST)</th>
      <th style="text-align: center">Session</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: center">14:00 - 14:20</td>
      <td style="text-align: center">Keynote (Kate Stanley &amp; Paolo Patierno @ IBM)</td>
    </tr>
    <tr>
      <td style="text-align: center">14:25 - 14:55</td>
      <td style="text-align: center">Beyond the Install: Take full ownership of your Strimzi cluster (Jakub Scholz @ Cloudera)</td>
    </tr>
    <tr>
      <td style="text-align: center">15:00 - 15:30</td>
      <td style="text-align: center">Who Are You? Configuring Kafka Authentication in Strimzi from TLS to Custom Principals (Daniel Mulder @ Axual)</td>
    </tr>
    <tr>
      <td style="text-align: center">15:35 - 16:05</td>
      <td style="text-align: center">Swapping the Engine Mid-Flight: How We Moved Reddit’s Petabyte Scale Kafka Fleet to Kubernetes (Sky Kistler @ Reddit)</td>
    </tr>
    <tr>
      <td style="text-align: center">16:10 - 16:40</td>
      <td style="text-align: center">Building Strimzi MCP Server for Kubernetes: Democratizing Platform Expertise Through LLMs (David Kornel, Jakub Stejskal @ IBM)</td>
    </tr>
    <tr>
      <td style="text-align: center">16:45 - 17:15</td>
      <td style="text-align: center">From Running to Operating: Real-World Strimzi in Production (Rajith Attapattu @ Randoli)</td>
    </tr>
    <tr>
      <td style="text-align: center">17:20 - 17:50</td>
      <td style="text-align: center">Disaster Recovery in action with Kafka and Strimzi (Mickael Maison, Gantigmaa Selenge @ IBM)</td>
    </tr>
    <tr>
      <td style="text-align: center">17:50 - 18:00</td>
      <td style="text-align: center">Closing (Kate Stanley &amp; Paolo Patierno @ IBM)</td>
    </tr>
  </tbody>
</table>

<p>For more details about speakers and sessions, see the <a href="https://community.cncf.io/events/details/cncf-virtual-project-events-hosted-by-cncf-presents-strimzicon-virtual-2026/">CNCF event page</a>.</p>

<p>We look forward to seeing you at the conference. <a href="https://community.cncf.io/events/details/cncf-virtual-project-events-hosted-by-cncf-presents-strimzicon-virtual-2026/">Register here</a>. It’s free!</p>]]></content><author><name>Paolo Patierno</name></author><summary type="html"><![CDATA[We are very pleased to announce the speakers and sessions for the third edition of StrimziCon! The interest from the community was really high and we received a lot of awesome proposals. The program committee found it really tough to choose among them in order to build an amazing agenda.]]></summary></entry><entry><title type="html">Video: What’s new in Strimzi 0.51.0</title><link href="https://strimzi.io/blog/2026/03/05/what-is-new-in-strimzi-0.51.0/" rel="alternate" type="text/html" title="Video: What’s new in Strimzi 0.51.0" /><published>2026-03-05T00:00:00+00:00</published><updated>2026-03-05T00:00:00+00:00</updated><id>https://strimzi.io/blog/2026/03/05/what-is-new-in-strimzi-0.51.0</id><content type="html" xml:base="https://strimzi.io/blog/2026/03/05/what-is-new-in-strimzi-0.51.0/"><![CDATA[<p>Strimzi 0.51.0 has been released with multiple new features and improvements.
As with previous releases, we created a video that introduces the main changes.
You can watch the video here or on our <a href="https://youtu.be/qHYpOhZACzY">YouTube channel</a> and check the <a href="https://github.com/strimzi/strimzi-kafka-operator/releases/tag/0.51.0">release notes</a>.</p>

<!--more-->

<iframe width="560" height="315" src="https://www.youtube.com/embed/qHYpOhZACzY" frameborder="0" allow="accelerometer; autoplay; encrypted-media; gyroscope; picture-in-picture" allowfullscreen=""></iframe>]]></content><author><name>Jakub Scholz</name></author><summary type="html"><![CDATA[Strimzi 0.51.0 has been released with multiple new features and improvements. As with previous releases, we created a video that introduces the main changes. You can watch the video here or on our YouTube channel and check the release notes.]]></summary></entry><entry><title type="html">Welcome StrimziCon 2026!</title><link href="https://strimzi.io/blog/2026/02/18/strimzicon2026-announcement/" rel="alternate" type="text/html" title="Welcome StrimziCon 2026!" /><published>2026-02-18T00:00:00+00:00</published><updated>2026-02-18T00:00:00+00:00</updated><id>https://strimzi.io/blog/2026/02/18/strimzicon2026-announcement</id><content type="html" xml:base="https://strimzi.io/blog/2026/02/18/strimzicon2026-announcement/"><![CDATA[<p>Following the success of <a href="https://strimzi.io/blog/2024/06/06/strimzicon2024-roundup/">StrimziCon 2024</a> and <a href="https://strimzi.io/blog/2025/06/16/strimzicon2025-roundup/">StrimziCon 2025</a>, we’re pleased to announce the third edition, scheduled for later this year!
As in previous years, the event is going to be focused on our beloved Strimzi and Apache Kafka projects and will be held <em>virtually</em>.
The event is organized by the Strimzi maintainers in collaboration with the <a href="https://www.cncf.io/">Cloud Native Computing Foundation (CNCF)</a>.</p>

<!--more-->

<p><img src="/assets/images/posts/2026-02-18-strimzicon2026-banner.png" alt="StrimziCon 2026 Banner" /></p>

<h3 id="why-attend-strimzicon">Why attend StrimziCon?</h3>

<p>StrimziCon is a community event for developers, DevOps engineers, and solution architects who want to learn about Strimzi and event streaming.
This event will bring together the Strimzi community to share real‑world use cases, best practices, and first‑hand experience from experts and users alike.
If you work with cloud-native technologies, and need to manage data in motion in a cloud-based environment, this event is for you.</p>

<p>The conference will take place on <b>Wednesday, June 3rd, 2026</b> (afternoon CEST).</p>

<p>The call for <b>speakers</b> is now open, and we’re eagerly awaiting your proposals to discuss:</p>

<ul>
  <li><b>Core Strimzi</b>: Deep dive into a specific component or feature.</li>
  <li><b>Case Studies</b>: Provide an overview of a use case or review of a real-world Strimzi deployment, highlighting difficulties, lessons learned, and key takeaways.</li>
  <li><b>Integrations</b>: Explore how Strimzi integrates with other open source or CNCF projects.</li>
  <li><b>Operations</b>: Share insights into what it takes to run Strimzi and maintain clusters in production.</li>
</ul>

<p>The submission deadline is March 31st, 2026.</p>

<h3 id="from-the-community-to-the-community">From the community to the community</h3>

<p>We encourage any community members to submit a talk: from a Strimzi deep dive, to how you operate and use it in production, through integrations with other projects.
From the community to the community, this is the best way to share.</p>

<p>Paolo Patierno and Kate Stanley, Strimzi maintainers and contributors, are organizing the conference with the CNCF team and will host the event.</p>

<p>All submitted sessions will be evaluated by the StrimziCon program committee.
The committee includes representatives from companies that use Strimzi in production.
We’ll have representatives from IBM, Ericsson, Reddit, Red Hat, and Elation Health Inc.:</p>

<ul>
  <li><a href="https://www.linkedin.com/in/paolopatierno/">Paolo Patierno</a> (Senior Principal Software Engineer @IBM)</li>
  <li><a href="https://www.linkedin.com/in/katherine-kate-stanley-3796b579/">Kate Stanley</a> (Principal Software Engineer @IBM)</li>
  <li><a href="https://www.linkedin.com/in/michael-morris-32a804324">Michael Morris</a> (Master Engineer @Ericsson)</li>
  <li><a href="https://www.linkedin.com/in/nickgarvey/">Nick Garvey</a> (Staff Software Engineer @Reddit)</li>
  <li><a href="https://www.linkedin.com/in/aliok/">Ali Ok</a> (Principal Software Engineer @Red Hat)</li>
  <li><a href="https://www.linkedin.com/in/liam-clarke-hutchinson-7770375/">Liam Clarke-Hutchinson</a> (Staff Software Enginner @Elation Health Inc.)</li>
  <li><a href="https://www.linkedin.com/in/scholzj/">Jakub Scholz</a> (Principal Engineer @Cloudera)</li>
  <li><a href="https://www.linkedin.com/in/mickaelmaison/">Mickael Maison</a> (Senior Principal Software Engineer @IBM)</li>
  <li><a href="https://www.linkedin.com/in/shubhamrwt/">Shubham Rawat</a> (Senior Software Engineer @IBM)</li>
</ul>

<p>The committee members will leverage their experience and knowledge on the project as users and contributors in order to select the best proposals and build an awesome agenda.</p>

<h3 id="join-us-propose-your-session-or-register-to-attend">Join us, propose your session or register to attend!</h3>

<p>You can find more details on the official <a href="https://community.cncf.io/events/details/cncf-virtual-project-events-hosted-by-cncf-presents-strimzicon-virtual-2026/">page</a> as part of the CNCF events.</p>

<p>Don’t forget to submit your proposal <a href="https://sessionize.com/StrimziConVirtual2026/">here</a>.</p>

<p>Even if you’re not considering presenting, we hope you will still join us as an attendee.</p>

<p>It’s virtual, it’s free, and it’s going to be epic again!
Join the Strimzi community at StrimziCon 2026!</p>]]></content><author><name>Paolo Patierno</name></author><summary type="html"><![CDATA[Following the success of StrimziCon 2024 and StrimziCon 2025, we’re pleased to announce the third edition, scheduled for later this year! As in previous years, the event is going to be focused on our beloved Strimzi and Apache Kafka projects and will be held virtually. The event is organized by the Strimzi maintainers in collaboration with the Cloud Native Computing Foundation (CNCF).]]></summary></entry><entry><title type="html">Server-Side Apply in Strimzi</title><link href="https://strimzi.io/blog/2026/01/26/server-side-apply-in-strimzi/" rel="alternate" type="text/html" title="Server-Side Apply in Strimzi" /><published>2026-01-26T00:00:00+00:00</published><updated>2026-01-26T00:00:00+00:00</updated><id>https://strimzi.io/blog/2026/01/26/server-side-apply-in-strimzi</id><content type="html" xml:base="https://strimzi.io/blog/2026/01/26/server-side-apply-in-strimzi/"><![CDATA[<p>Kubernetes operators create, update, and delete resources to reflect the desired state defined by users.
When a particular resource is managed by a single operator or a single user, update conflicts are relatively rare. 
However, problems arise when multiple actors - such as different operators or automation tools - modify the same resource.</p>

<p>With client-side apply, even changes to different fields can unintentionally overwrite each other. 
This behavior is especially problematic when multiple reconciliation loops are involved, as one operator may repeatedly revert changes made by another. 
This is the case with client-side apply as used in Strimzi.</p>

<h3 id="client-side-apply-in-strimzi">Client-side apply in Strimzi</h3>

<p>When a user creates or updates a Strimzi resource, the desired state is taken by Strimzi and propagated into all needed resources.
For example (based on the configuration), when a user updates a field in the <code class="language-plaintext highlighter-rouge">Kafka</code> CR, Strimzi rebuilds the desired state for resources like <code class="language-plaintext highlighter-rouge">StrimziPodSet</code>, <code class="language-plaintext highlighter-rouge">ConfigMap</code>, <code class="language-plaintext highlighter-rouge">Service</code>, and <code class="language-plaintext highlighter-rouge">PersistentVolumeClaim</code>.
This is completely fine until another operator, running in a reconciliation loop, updates these resources with another value.
One example is Kyverno, which has a policy to add annotation <code class="language-plaintext highlighter-rouge">policies.kyverno.io/last-applied-patches:...</code> to all resources in the Kubernetes cluster using <code class="language-plaintext highlighter-rouge">MutatingWebhookConfiguration</code>.
With each update, Strimzi detects the resource change and reconciles it from the desired state, overwriting any modifications made by the other operator.
This can result in an update loop, along with warnings, errors, or other downstream issues in affected services or operators.</p>

<p>Because of these issues, we decided to add support for Server-Side Apply.</p>

<h3 id="what-is-server-side-apply">What is Server-Side Apply?</h3>

<p>Server-Side Apply (SSA) allows multiple actors to update the same Kubernetes resource while managing different fields. 
Instead of applying a full object update, each actor applies only the fields it owns, identified by a field manager. 
Kubernetes then tracks field ownership and detects conflicts when multiple actors attempt to manage the same field.</p>

<p>For operators, this provides a clear ownership model. 
The Strimzi operator can manage only the fields it’s responsible for, without overwriting changes made to other fields by users or other controllers.</p>

<p>At the same time, this model assumes that other actors modify only the fields that they are responsible for. 
If process external to Strimzi updates fields that are essential for Strimzi’s functionality, Strimzi will revert the changes back. 
However, SSA makes these ownership boundaries explicit and visible, helping surface such issues earlier and making them easier to understand and address.</p>

<h3 id="incremental-implementation-of-server-side-apply-in-strimzi">Incremental implementation of Server-Side Apply in Strimzi</h3>

<p>Originally, there was a <a href="https://github.com/strimzi/proposals/blob/main/052-k8s-server-side-apply.md">proposal</a> and a plan to implement Server-Side Apply for all resources managed by Strimzi. 
However, the scope of such a change turned out to be too large, so we decided (in <a href="https://github.com/strimzi/proposals/blob/main/105-server-side-apply-implementation-fg-timelines.md">second proposal</a>) to split the implementation into multiple phases.</p>

<h4 id="phase-1-initial-server-side-apply-support">Phase 1: Initial Server-Side Apply support</h4>

<p>Server-Side Apply support was introduced in Strimzi 0.48 behind a feature gate, and its adoption is being implemented incrementally.</p>

<p>In the first phase, we implemented Server-Side Apply for the following resources:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">PersistentVolumeClaim</code></li>
  <li><code class="language-plaintext highlighter-rouge">ServiceAccount</code></li>
  <li><code class="language-plaintext highlighter-rouge">Service</code></li>
  <li><code class="language-plaintext highlighter-rouge">Ingress</code></li>
  <li><code class="language-plaintext highlighter-rouge">ConfigMap</code></li>
</ul>

<p>These resources were identified as the most problematic based on GitHub issues, community discussions, and feedback from users on the Strimzi community Slack channels. 
To minimize risk and avoid unexpected behavior, switching to Server-Side Apply is gated behind a feature gate called <code class="language-plaintext highlighter-rouge">ServerSideApplyPhase1</code>.</p>

<p>When this feature gate is enabled, the Cluster Operator uses Server-Side Apply (SSA) exclusively for these resources, applying declarative updates, such as changes to metadata, spec, and status, rather than rebuilding the entire resource from scratch.
The SSA implementation in Strimzi ensures that fields managed by Strimzi are always reconciled to the desired state, even in the presence of conflicts.</p>

<p>The reconciliation flow is as follows:</p>

<ul>
  <li>Strimzi first attempts to apply the change using Server-Side Apply without forcing ownership.</li>
  <li>If no conflict occurs, the patch is applied and reconciliation continues.</li>
  <li>If a conflict is detected, the Cluster Operator logs the error and retries the apply operation with force enabled.</li>
  <li>When force is used, the affected field is updated, overwriting any changes made by other actors, and an explicit log entry is emitted to make this behavior visible to users.</li>
</ul>

<p>This approach ensures that Strimzi can reliably configure the fields required for correct cluster functionality, while still allowing other actors to manage fields outside of Strimzi’s ownership.</p>

<h3 id="how-server-side-apply-works-in-practice">How Server-Side Apply works in practice</h3>

<p>Theory is nice, but let’s see Server-Side Apply in action.
To try out this feature, you first need to enable the <code class="language-plaintext highlighter-rouge">ServerSideApplyPhase1</code> feature gate in the <a href="https://github.com/strimzi/strimzi-kafka-operator/blob/main/install/cluster-operator/060-Deployment-strimzi-cluster-operator.yaml#L90"><code class="language-plaintext highlighter-rouge">Deployment</code> resource</a> for the Strimzi Cluster Operator:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nn">...</span>
<span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">STRIMZI_FEATURE_GATES</span>
  <span class="na">value</span><span class="pi">:</span> <span class="s2">"</span><span class="s">+ServerSideApplyPhase1"</span>
<span class="nn">...</span>
</code></pre></div></div>

<p>With Server-Side Apply enabled in the Cluster Operator, it can be tested on one of the phase 1 SSA resources.
For this example, an ephemeral Kafka cluster is created from <a href="https://github.com/strimzi/strimzi-kafka-operator/blob/main/examples/kafka/kafka-ephemeral.yaml">the configuration examples</a> provided with Strimzi.</p>

<p>As a simple test case, a custom annotation is added to the <code class="language-plaintext highlighter-rouge">-kafka-bootstrap</code> Service. 
Before doing that, let’s inspect the current <code class="language-plaintext highlighter-rouge">.metadata</code> section of the resource.</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="o">&gt;</span> kubectl get service
NAME                         TYPE        CLUSTER-IP      EXTERNAL-IP   PORT<span class="o">(</span>S<span class="o">)</span>                                        AGE
my-cluster-kafka-bootstrap   ClusterIP   X.X.X.X         &lt;none&gt;        9091/TCP,9092/TCP,9093/TCP                     9m17s
my-cluster-kafka-brokers     ClusterIP   None            &lt;none&gt;        9090/TCP,9091/TCP,8443/TCP,9092/TCP,9093/TCP   9m17s

<span class="o">&gt;</span> kubectl get service my-cluster-kafka-bootstrap <span class="nt">-o</span> <span class="nv">jsonpath</span><span class="o">=</span><span class="s1">'{.metadata}'</span> | jq
<span class="o">{</span>
  <span class="s2">"annotations"</span>: <span class="o">{</span>
    <span class="s2">"strimzi.io/discovery"</span>: <span class="s2">"[ {</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">port</span><span class="se">\"</span><span class="s2"> : 9092,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">tls</span><span class="se">\"</span><span class="s2"> : false,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">protocol</span><span class="se">\"</span><span class="s2"> : </span><span class="se">\"</span><span class="s2">kafka</span><span class="se">\"</span><span class="s2">,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">auth</span><span class="se">\"</span><span class="s2"> : </span><span class="se">\"</span><span class="s2">none</span><span class="se">\"\n</span><span class="s2">}, {</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">port</span><span class="se">\"</span><span class="s2"> : 9093,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">tls</span><span class="se">\"</span><span class="s2"> : true,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">protocol</span><span class="se">\"</span><span class="s2"> : </span><span class="se">\"</span><span class="s2">kafka</span><span class="se">\"</span><span class="s2">,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">auth</span><span class="se">\"</span><span class="s2"> : </span><span class="se">\"</span><span class="s2">none</span><span class="se">\"\n</span><span class="s2">} ]"</span>
  <span class="o">}</span>,
  ...
  <span class="s2">"managedFields"</span>: <span class="o">[</span>
    <span class="o">{</span>
      <span class="s2">"apiVersion"</span>: <span class="s2">"v1"</span>,
      <span class="s2">"fieldsType"</span>: <span class="s2">"FieldsV1"</span>,
      <span class="s2">"fieldsV1"</span>: <span class="o">{</span>
        <span class="s2">"f:metadata"</span>: <span class="o">{</span>
          <span class="s2">"f:annotations"</span>: <span class="o">{</span>
            <span class="s2">"f:strimzi.io/discovery"</span>: <span class="o">{}</span>
          <span class="o">}</span>,
          ...
      <span class="s2">"manager"</span>: <span class="s2">"strimzi-kafka-operator"</span>,
      <span class="s2">"operation"</span>: <span class="s2">"Apply"</span>
    <span class="o">}</span>,
    ...
  <span class="o">]</span>
<span class="o">}</span>
</code></pre></div></div>

<p>At this point, the Service contains a single annotation, <code class="language-plaintext highlighter-rouge">strimzi.io/discovery</code>.
The <code class="language-plaintext highlighter-rouge">managedFields</code> section shows that this annotation is owned by the <code class="language-plaintext highlighter-rouge">strimzi-kafka-operator</code> field manager and was applied using Server-Side Apply.</p>

<p>Now let’s simulate another actor updating the same resource by adding a custom annotation using SSA - in our case it will be <code class="language-plaintext highlighter-rouge">my.annotation/some: value</code>.</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="o">&gt;</span> kubectl apply <span class="nt">--server-side</span> <span class="nt">--field-manager</span><span class="o">=</span>different-agent <span class="nt">-f</span> - <span class="o">&lt;&lt;</span><span class="no">EOF</span><span class="sh">
apiVersion: v1
kind: Service
metadata:
  annotations:
    my.annotation/some: value # add new annotation
    strimzi.io/discovery: |-
      [ {
        "port" : 9092,
        "tls" : false,
        "protocol" : "kafka",
        "auth" : "none"
      }, {
        "port" : 9093,
        "tls" : true,
        "protocol" : "kafka",
        "auth" : "none"
      } ]
  labels:
    app.kubernetes.io/instance: my-cluster
    app.kubernetes.io/managed-by: strimzi-cluster-operator
    app.kubernetes.io/name: kafka
    app.kubernetes.io/part-of: strimzi-my-cluster
    strimzi.io/cluster: my-cluster
    strimzi.io/component-type: kafka
    strimzi.io/discovery: "true"
    strimzi.io/kind: Kafka
    strimzi.io/name: my-cluster-kafka
  name: my-cluster-kafka-bootstrap
  namespace: test
spec:
  clusterIP: 10.97.174.54
  clusterIPs:
  - 10.97.174.54
  internalTrafficPolicy: Cluster
  ipFamilies:
  - IPv4
  ipFamilyPolicy: SingleStack
  ports:
  - name: tcp-replication
    port: 9091
    protocol: TCP
    targetPort: tcp-replication
  - name: tcp-clients
    port: 9092
    protocol: TCP
    targetPort: tcp-clients
  - name: tcp-clientstls
    port: 9093
    protocol: TCP
    targetPort: tcp-clientstls
  selector:
    strimzi.io/broker-role: "true"
    strimzi.io/cluster: my-cluster
    strimzi.io/kind: Kafka
    strimzi.io/name: my-cluster-kafka
  sessionAffinity: None
  type: ClusterIP
</span><span class="no">EOF
</span></code></pre></div></div>

<p>The <code class="language-plaintext highlighter-rouge">--field-manager</code> flag identifies the actor performing the change.
If we inspect the metadata again, we can see that the annotation was added and is now owned by a different field manager.</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="o">&gt;</span> kubectl get service my-cluster-kafka-bootstrap <span class="nt">-o</span> <span class="nv">jsonpath</span><span class="o">=</span><span class="s1">'{.metadata}'</span> | jq
<span class="o">{</span>
  <span class="s2">"annotations"</span>: <span class="o">{</span>
    <span class="s2">"my.annotation/some"</span>: <span class="s2">"value"</span>,
    <span class="s2">"strimzi.io/discovery"</span>: <span class="s2">"[ {</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">port</span><span class="se">\"</span><span class="s2"> : 9092,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">tls</span><span class="se">\"</span><span class="s2"> : false,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">protocol</span><span class="se">\"</span><span class="s2"> : </span><span class="se">\"</span><span class="s2">kafka</span><span class="se">\"</span><span class="s2">,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">auth</span><span class="se">\"</span><span class="s2"> : </span><span class="se">\"</span><span class="s2">none</span><span class="se">\"\n</span><span class="s2">}, {</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">port</span><span class="se">\"</span><span class="s2"> : 9093,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">tls</span><span class="se">\"</span><span class="s2"> : true,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">protocol</span><span class="se">\"</span><span class="s2"> : </span><span class="se">\"</span><span class="s2">kafka</span><span class="se">\"</span><span class="s2">,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">auth</span><span class="se">\"</span><span class="s2"> : </span><span class="se">\"</span><span class="s2">none</span><span class="se">\"\n</span><span class="s2">} ]"</span>
  <span class="o">}</span>,
  ...
  <span class="s2">"managedFields"</span>: <span class="o">[</span>
    ...
    <span class="o">{</span>
      <span class="s2">"apiVersion"</span>: <span class="s2">"v1"</span>,
      <span class="s2">"fieldsType"</span>: <span class="s2">"FieldsV1"</span>,
      <span class="s2">"fieldsV1"</span>: <span class="o">{</span>
        <span class="s2">"f:metadata"</span>: <span class="o">{</span>
          <span class="s2">"f:annotations"</span>: <span class="o">{</span>
            <span class="s2">"f:my.annotation/some"</span>: <span class="o">{}</span>
          <span class="o">}</span>
        <span class="o">}</span>
      <span class="o">}</span>,
      <span class="s2">"manager"</span>: <span class="s2">"different-agent"</span>,
      <span class="s2">"operation"</span>: <span class="s2">"Update"</span>,
      <span class="s2">"time"</span>: <span class="s2">"2026-01-14T00:54:46Z"</span>
    <span class="o">}</span>
</code></pre></div></div>

<p>Without Server-Side Apply, Strimzi would not track ownership of individual fields, and this custom annotation would likely be removed during the next reconciliation.</p>

<h4 id="handling-conflicts">Handling conflicts</h4>

<p>Now let’s see what happens when another actor attempts to modify a field owned by Strimzi.
In this case, you will need to use <code class="language-plaintext highlighter-rouge">--force-conflicts</code>, as the field we are trying to update is managed by Strimzi.</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="o">&gt;</span> kubectl apply <span class="nt">--server-side</span> <span class="nt">--field-manager</span><span class="o">=</span>different-agent <span class="nt">--force-conflicts</span> <span class="nt">-f</span> - <span class="o">&lt;&lt;</span><span class="no">EOF</span><span class="sh">
apiVersion: v1
kind: Service
metadata:
  annotations:
    my.annotation/some: value # keep the annotation
    strimzi.io/discovery: "this-is-wrong" # change the annotation managed by Strimzi
  labels:
    app.kubernetes.io/instance: my-cluster
    app.kubernetes.io/managed-by: strimzi-cluster-operator
    app.kubernetes.io/name: kafka
    app.kubernetes.io/part-of: strimzi-my-cluster
    strimzi.io/cluster: my-cluster
    strimzi.io/component-type: kafka
    strimzi.io/discovery: "true"
    strimzi.io/kind: Kafka
    strimzi.io/name: my-cluster-kafka
  name: my-cluster-kafka-bootstrap
  namespace: test
spec:
  clusterIP: 10.97.174.54
  clusterIPs:
  - 10.97.174.54
  internalTrafficPolicy: Cluster
  ipFamilies:
  - IPv4
  ipFamilyPolicy: SingleStack
  ports:
  - name: tcp-replication
    port: 9091
    protocol: TCP
    targetPort: tcp-replication
  - name: tcp-clients
    port: 9092
    protocol: TCP
    targetPort: tcp-clients
  - name: tcp-clientstls
    port: 9093
    protocol: TCP
    targetPort: tcp-clientstls
  selector:
    strimzi.io/broker-role: "true"
    strimzi.io/cluster: my-cluster
    strimzi.io/kind: Kafka
    strimzi.io/name: my-cluster-kafka
  sessionAffinity: None
  type: ClusterIP
</span><span class="no">EOF
</span></code></pre></div></div>

<p>At this point, the annotation is updated (as we used force apply):</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="o">&gt;</span> kubectl get service my-cluster-kafka-bootstrap <span class="nt">-o</span> <span class="nv">jsonpath</span><span class="o">=</span><span class="s1">'{.metadata}'</span> | jq
<span class="o">{</span>
  <span class="s2">"annotations"</span>: <span class="o">{</span>
    <span class="s2">"my.annotation/some"</span>: <span class="s2">"value"</span>,
    <span class="s2">"strimzi.io/discovery"</span>: <span class="s2">"this-is-wrong"</span>
  <span class="o">}</span>,
  ...
<span class="o">}</span>
</code></pre></div></div>

<p>During the next reconciliation, Strimzi detects a conflict on the <code class="language-plaintext highlighter-rouge">strimzi.io/discovery</code> annotation. 
Since this field is owned by Strimzi, the operator logs a warning and retries the apply operation with <code class="language-plaintext highlighter-rouge">force</code> enabled:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>2026-01-14 01:01:09 DEBUG AbstractNamespacedResourceOperator:280 - Reconciliation <span class="c">#68(timer) Kafka(test-suite-namespace/my-cluster): Service test-suite-namespace/my-cluster-kafka-bootstrap is being patched using Server Side Apply</span>
2026-01-14 01:01:09 WARN  AbstractNamespacedResourceOperator:286 - Reconciliation <span class="c">#68(timer) Kafka(test-suite-namespace/my-cluster): Service test-suite-namespace/my-cluster-kafka-bootstrap failed to patch because of conflict: Failure executing: PATCH at: https://X.X.X.X:443/api/v1/namespaces/test-suite-namespace/services/my-cluster-kafka-bootstrap?fieldManager=strimzi-kafka-operator&amp;force=false. Message: Apply failed with 1 conflict: conflict with "different-agent" using v1: .metadata.annotations.strimzi.io/discovery. Received status: Status(apiVersion=v1, code=409, details=StatusDetails(causes=[StatusCause(field=.metadata.annotations.strimzi.io/discovery, message=conflict with "different-agent" using v1, reason=FieldManagerConflict, additionalProperties={})], group=null, kind=null, name=null, retryAfterSeconds=null, uid=null, additionalProperties={}), kind=Status, message=Apply failed with 1 conflict: conflict with "different-agent" using v1: .metadata.annotations.strimzi.io/discovery, metadata=ListMeta(_continue=null, remainingItemCount=null, resourceVersion=null, selfLink=null, additionalProperties={}), reason=Conflict, status=Failure, additionalProperties={})., applying force</span>
</code></pre></div></div>

<p>After the forced apply, Strimzi restores the correct value of its managed annotation, while the custom annotation remains untouched:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="o">&gt;</span> kubectl get service my-cluster-kafka-bootstrap <span class="nt">-o</span> <span class="nv">jsonpath</span><span class="o">=</span><span class="s1">'{.metadata}'</span> | jq
<span class="o">{</span>
  <span class="s2">"annotations"</span>: <span class="o">{</span>
    <span class="s2">"my.annotation/some"</span>: <span class="s2">"value"</span>,
    <span class="s2">"strimzi.io/discovery"</span>: <span class="s2">"[ {</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">port</span><span class="se">\"</span><span class="s2"> : 9092,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">tls</span><span class="se">\"</span><span class="s2"> : false,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">protocol</span><span class="se">\"</span><span class="s2"> : </span><span class="se">\"</span><span class="s2">kafka</span><span class="se">\"</span><span class="s2">,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">auth</span><span class="se">\"</span><span class="s2"> : </span><span class="se">\"</span><span class="s2">none</span><span class="se">\"\n</span><span class="s2">}, {</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">port</span><span class="se">\"</span><span class="s2"> : 9093,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">tls</span><span class="se">\"</span><span class="s2"> : true,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">protocol</span><span class="se">\"</span><span class="s2"> : </span><span class="se">\"</span><span class="s2">kafka</span><span class="se">\"</span><span class="s2">,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">auth</span><span class="se">\"</span><span class="s2"> : </span><span class="se">\"</span><span class="s2">none</span><span class="se">\"\n</span><span class="s2">} ]"</span>
  <span class="o">}</span>,
  ...
<span class="o">}</span>
</code></pre></div></div>

<p>This example demonstrates how Server-Side Apply allows Strimzi to reliably enforce the fields it owns, while safely coexisting with other actors managing the same resource.</p>

<h4 id="removal-of-fields">Removal of fields</h4>

<p>In Server-Side Apply, every actor have a possibility to remove the fields - but only those they manage.
That means, in case that Strimzi owns the <code class="language-plaintext highlighter-rouge">strimzi.io/discovery</code> annotation and we want to remove it with our <code class="language-plaintext highlighter-rouge">different-agent</code> field manager, the field will not be deleted after the update.
Only the <code class="language-plaintext highlighter-rouge">my.annotation/some</code> will be removed, as it is owned by <code class="language-plaintext highlighter-rouge">different-agent</code> field manager:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="o">&gt;</span> kubectl apply <span class="nt">--server-side</span> <span class="nt">--field-manager</span><span class="o">=</span>different-agent <span class="nt">-f</span> - <span class="o">&lt;&lt;</span><span class="no">EOF</span><span class="sh">
apiVersion: v1
kind: Service
metadata:
  annotations: {} # set annotations to null
  labels:
    app.kubernetes.io/instance: my-cluster
    app.kubernetes.io/managed-by: strimzi-cluster-operator
    app.kubernetes.io/name: kafka
    app.kubernetes.io/part-of: strimzi-my-cluster
    strimzi.io/cluster: my-cluster
    strimzi.io/component-type: kafka
    strimzi.io/discovery: "true"
    strimzi.io/kind: Kafka
    strimzi.io/name: my-cluster-kafka
  name: my-cluster-kafka-bootstrap
  namespace: test
spec:
  clusterIP: 10.97.174.54
  clusterIPs:
  - 10.97.174.54
  internalTrafficPolicy: Cluster
  ipFamilies:
  - IPv4
  ipFamilyPolicy: SingleStack
  ports:
  - name: tcp-replication
    port: 9091
    protocol: TCP
    targetPort: tcp-replication
  - name: tcp-clients
    port: 9092
    protocol: TCP
    targetPort: tcp-clients
  - name: tcp-clientstls
    port: 9093
    protocol: TCP
    targetPort: tcp-clientstls
  selector:
    strimzi.io/broker-role: "true"
    strimzi.io/cluster: my-cluster
    strimzi.io/kind: Kafka
    strimzi.io/name: my-cluster-kafka
  sessionAffinity: None
  type: ClusterIP
</span><span class="no">EOF
</span></code></pre></div></div>

<p>The <code class="language-plaintext highlighter-rouge">annotations</code> field in the <code class="language-plaintext highlighter-rouge">Service</code> after the apply looks like this:</p>
<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="o">&gt;</span> kubectl get service my-cluster-kafka-bootstrap <span class="nt">-o</span> <span class="nv">jsonpath</span><span class="o">=</span><span class="s1">'{.metadata}'</span> | jq
<span class="o">{</span>
  <span class="s2">"annotations"</span>: <span class="o">{</span>
    <span class="s2">"strimzi.io/discovery"</span>: <span class="s2">"[ {</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">port</span><span class="se">\"</span><span class="s2"> : 9092,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">tls</span><span class="se">\"</span><span class="s2"> : false,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">protocol</span><span class="se">\"</span><span class="s2"> : </span><span class="se">\"</span><span class="s2">kafka</span><span class="se">\"</span><span class="s2">,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">auth</span><span class="se">\"</span><span class="s2"> : </span><span class="se">\"</span><span class="s2">none</span><span class="se">\"\n</span><span class="s2">}, {</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">port</span><span class="se">\"</span><span class="s2"> : 9093,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">tls</span><span class="se">\"</span><span class="s2"> : true,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">protocol</span><span class="se">\"</span><span class="s2"> : </span><span class="se">\"</span><span class="s2">kafka</span><span class="se">\"</span><span class="s2">,</span><span class="se">\n</span><span class="s2">  </span><span class="se">\"</span><span class="s2">auth</span><span class="se">\"</span><span class="s2"> : </span><span class="se">\"</span><span class="s2">none</span><span class="se">\"\n</span><span class="s2">} ]"</span>
  <span class="o">}</span>,
  ...
<span class="o">}</span>
</code></pre></div></div>

<h3 id="conclusion">Conclusion</h3>

<p>In this blog post, we described Server-Side Apply, how Strimzi uses it, how to enable it, and how it can simplify working with Strimzi — especially in environments where multiple operators modify the same Kubernetes resources.
Although Server-Side Apply has been available in Strimzi since version 0.48.0, it is still in the alpha stage and ready for broader testing.
We plan to move it to beta (enabled by default) in next version - Strimzi 0.51.0.
In case that you will find any issue with the implementation, or have suggestions related to Server-Side Apply in Strimzi, you can share your feedback with us on <a href="https://slack.cncf.io/">Slack</a>, or by opening <a href="https://github.com/orgs/strimzi/discussions">a discussion</a> or <a href="https://github.com/strimzi/strimzi-kafka-operator/issues">an issue</a> on GitHub.</p>]]></content><author><name>Lukas Kral</name></author><summary type="html"><![CDATA[Kubernetes operators create, update, and delete resources to reflect the desired state defined by users. When a particular resource is managed by a single operator or a single user, update conflicts are relatively rare. However, problems arise when multiple actors - such as different operators or automation tools - modify the same resource. With client-side apply, even changes to different fields can unintentionally overwrite each other. This behavior is especially problematic when multiple reconciliation loops are involved, as one operator may repeatedly revert changes made by another. This is the case with client-side apply as used in Strimzi. Client-side apply in Strimzi When a user creates or updates a Strimzi resource, the desired state is taken by Strimzi and propagated into all needed resources. For example (based on the configuration), when a user updates a field in the Kafka CR, Strimzi rebuilds the desired state for resources like StrimziPodSet, ConfigMap, Service, and PersistentVolumeClaim. This is completely fine until another operator, running in a reconciliation loop, updates these resources with another value. One example is Kyverno, which has a policy to add annotation policies.kyverno.io/last-applied-patches:... to all resources in the Kubernetes cluster using MutatingWebhookConfiguration. With each update, Strimzi detects the resource change and reconciles it from the desired state, overwriting any modifications made by the other operator. This can result in an update loop, along with warnings, errors, or other downstream issues in affected services or operators. Because of these issues, we decided to add support for Server-Side Apply. What is Server-Side Apply? Server-Side Apply (SSA) allows multiple actors to update the same Kubernetes resource while managing different fields. Instead of applying a full object update, each actor applies only the fields it owns, identified by a field manager. Kubernetes then tracks field ownership and detects conflicts when multiple actors attempt to manage the same field. For operators, this provides a clear ownership model. The Strimzi operator can manage only the fields it’s responsible for, without overwriting changes made to other fields by users or other controllers. At the same time, this model assumes that other actors modify only the fields that they are responsible for. If process external to Strimzi updates fields that are essential for Strimzi’s functionality, Strimzi will revert the changes back. However, SSA makes these ownership boundaries explicit and visible, helping surface such issues earlier and making them easier to understand and address. Incremental implementation of Server-Side Apply in Strimzi Originally, there was a proposal and a plan to implement Server-Side Apply for all resources managed by Strimzi. However, the scope of such a change turned out to be too large, so we decided (in second proposal) to split the implementation into multiple phases. Phase 1: Initial Server-Side Apply support Server-Side Apply support was introduced in Strimzi 0.48 behind a feature gate, and its adoption is being implemented incrementally. In the first phase, we implemented Server-Side Apply for the following resources: PersistentVolumeClaim ServiceAccount Service Ingress ConfigMap These resources were identified as the most problematic based on GitHub issues, community discussions, and feedback from users on the Strimzi community Slack channels. To minimize risk and avoid unexpected behavior, switching to Server-Side Apply is gated behind a feature gate called ServerSideApplyPhase1. When this feature gate is enabled, the Cluster Operator uses Server-Side Apply (SSA) exclusively for these resources, applying declarative updates, such as changes to metadata, spec, and status, rather than rebuilding the entire resource from scratch. The SSA implementation in Strimzi ensures that fields managed by Strimzi are always reconciled to the desired state, even in the presence of conflicts. The reconciliation flow is as follows: Strimzi first attempts to apply the change using Server-Side Apply without forcing ownership. If no conflict occurs, the patch is applied and reconciliation continues. If a conflict is detected, the Cluster Operator logs the error and retries the apply operation with force enabled. When force is used, the affected field is updated, overwriting any changes made by other actors, and an explicit log entry is emitted to make this behavior visible to users. This approach ensures that Strimzi can reliably configure the fields required for correct cluster functionality, while still allowing other actors to manage fields outside of Strimzi’s ownership. How Server-Side Apply works in practice Theory is nice, but let’s see Server-Side Apply in action. To try out this feature, you first need to enable the ServerSideApplyPhase1 feature gate in the Deployment resource for the Strimzi Cluster Operator: ... - name: STRIMZI_FEATURE_GATES value: "+ServerSideApplyPhase1" ... With Server-Side Apply enabled in the Cluster Operator, it can be tested on one of the phase 1 SSA resources. For this example, an ephemeral Kafka cluster is created from the configuration examples provided with Strimzi. As a simple test case, a custom annotation is added to the -kafka-bootstrap Service. Before doing that, let’s inspect the current .metadata section of the resource. &gt; kubectl get service NAME TYPE CLUSTER-IP EXTERNAL-IP PORT(S) AGE my-cluster-kafka-bootstrap ClusterIP X.X.X.X &lt;none&gt; 9091/TCP,9092/TCP,9093/TCP 9m17s my-cluster-kafka-brokers ClusterIP None &lt;none&gt; 9090/TCP,9091/TCP,8443/TCP,9092/TCP,9093/TCP 9m17s &gt; kubectl get service my-cluster-kafka-bootstrap -o jsonpath='{.metadata}' | jq { "annotations": { "strimzi.io/discovery": "[ {\n \"port\" : 9092,\n \"tls\" : false,\n \"protocol\" : \"kafka\",\n \"auth\" : \"none\"\n}, {\n \"port\" : 9093,\n \"tls\" : true,\n \"protocol\" : \"kafka\",\n \"auth\" : \"none\"\n} ]" }, ... "managedFields": [ { "apiVersion": "v1", "fieldsType": "FieldsV1", "fieldsV1": { "f:metadata": { "f:annotations": { "f:strimzi.io/discovery": {} }, ... "manager": "strimzi-kafka-operator", "operation": "Apply" }, ... ] } At this point, the Service contains a single annotation, strimzi.io/discovery. The managedFields section shows that this annotation is owned by the strimzi-kafka-operator field manager and was applied using Server-Side Apply. Now let’s simulate another actor updating the same resource by adding a custom annotation using SSA - in our case it will be my.annotation/some: value. &gt; kubectl apply --server-side --field-manager=different-agent -f - &lt;&lt;EOF apiVersion: v1 kind: Service metadata: annotations: my.annotation/some: value # add new annotation strimzi.io/discovery: |- [ { "port" : 9092, "tls" : false, "protocol" : "kafka", "auth" : "none" }, { "port" : 9093, "tls" : true, "protocol" : "kafka", "auth" : "none" } ] labels: app.kubernetes.io/instance: my-cluster app.kubernetes.io/managed-by: strimzi-cluster-operator app.kubernetes.io/name: kafka app.kubernetes.io/part-of: strimzi-my-cluster strimzi.io/cluster: my-cluster strimzi.io/component-type: kafka strimzi.io/discovery: "true" strimzi.io/kind: Kafka strimzi.io/name: my-cluster-kafka name: my-cluster-kafka-bootstrap namespace: test spec: clusterIP: 10.97.174.54 clusterIPs: - 10.97.174.54 internalTrafficPolicy: Cluster ipFamilies: - IPv4 ipFamilyPolicy: SingleStack ports: - name: tcp-replication port: 9091 protocol: TCP targetPort: tcp-replication - name: tcp-clients port: 9092 protocol: TCP targetPort: tcp-clients - name: tcp-clientstls port: 9093 protocol: TCP targetPort: tcp-clientstls selector: strimzi.io/broker-role: "true" strimzi.io/cluster: my-cluster strimzi.io/kind: Kafka strimzi.io/name: my-cluster-kafka sessionAffinity: None type: ClusterIP EOF The --field-manager flag identifies the actor performing the change. If we inspect the metadata again, we can see that the annotation was added and is now owned by a different field manager. &gt; kubectl get service my-cluster-kafka-bootstrap -o jsonpath='{.metadata}' | jq { "annotations": { "my.annotation/some": "value", "strimzi.io/discovery": "[ {\n \"port\" : 9092,\n \"tls\" : false,\n \"protocol\" : \"kafka\",\n \"auth\" : \"none\"\n}, {\n \"port\" : 9093,\n \"tls\" : true,\n \"protocol\" : \"kafka\",\n \"auth\" : \"none\"\n} ]" }, ... "managedFields": [ ... { "apiVersion": "v1", "fieldsType": "FieldsV1", "fieldsV1": { "f:metadata": { "f:annotations": { "f:my.annotation/some": {} } } }, "manager": "different-agent", "operation": "Update", "time": "2026-01-14T00:54:46Z" } Without Server-Side Apply, Strimzi would not track ownership of individual fields, and this custom annotation would likely be removed during the next reconciliation. Handling conflicts Now let’s see what happens when another actor attempts to modify a field owned by Strimzi. In this case, you will need to use --force-conflicts, as the field we are trying to update is managed by Strimzi. &gt; kubectl apply --server-side --field-manager=different-agent --force-conflicts -f - &lt;&lt;EOF apiVersion: v1 kind: Service metadata: annotations: my.annotation/some: value # keep the annotation strimzi.io/discovery: "this-is-wrong" # change the annotation managed by Strimzi labels: app.kubernetes.io/instance: my-cluster app.kubernetes.io/managed-by: strimzi-cluster-operator app.kubernetes.io/name: kafka app.kubernetes.io/part-of: strimzi-my-cluster strimzi.io/cluster: my-cluster strimzi.io/component-type: kafka strimzi.io/discovery: "true" strimzi.io/kind: Kafka strimzi.io/name: my-cluster-kafka name: my-cluster-kafka-bootstrap namespace: test spec: clusterIP: 10.97.174.54 clusterIPs: - 10.97.174.54 internalTrafficPolicy: Cluster ipFamilies: - IPv4 ipFamilyPolicy: SingleStack ports: - name: tcp-replication port: 9091 protocol: TCP targetPort: tcp-replication - name: tcp-clients port: 9092 protocol: TCP targetPort: tcp-clients - name: tcp-clientstls port: 9093 protocol: TCP targetPort: tcp-clientstls selector: strimzi.io/broker-role: "true" strimzi.io/cluster: my-cluster strimzi.io/kind: Kafka strimzi.io/name: my-cluster-kafka sessionAffinity: None type: ClusterIP EOF At this point, the annotation is updated (as we used force apply): &gt; kubectl get service my-cluster-kafka-bootstrap -o jsonpath='{.metadata}' | jq { "annotations": { "my.annotation/some": "value", "strimzi.io/discovery": "this-is-wrong" }, ... } During the next reconciliation, Strimzi detects a conflict on the strimzi.io/discovery annotation. Since this field is owned by Strimzi, the operator logs a warning and retries the apply operation with force enabled: 2026-01-14 01:01:09 DEBUG AbstractNamespacedResourceOperator:280 - Reconciliation #68(timer) Kafka(test-suite-namespace/my-cluster): Service test-suite-namespace/my-cluster-kafka-bootstrap is being patched using Server Side Apply 2026-01-14 01:01:09 WARN AbstractNamespacedResourceOperator:286 - Reconciliation #68(timer) Kafka(test-suite-namespace/my-cluster): Service test-suite-namespace/my-cluster-kafka-bootstrap failed to patch because of conflict: Failure executing: PATCH at: https://X.X.X.X:443/api/v1/namespaces/test-suite-namespace/services/my-cluster-kafka-bootstrap?fieldManager=strimzi-kafka-operator&amp;force=false. Message: Apply failed with 1 conflict: conflict with "different-agent" using v1: .metadata.annotations.strimzi.io/discovery. Received status: Status(apiVersion=v1, code=409, details=StatusDetails(causes=[StatusCause(field=.metadata.annotations.strimzi.io/discovery, message=conflict with "different-agent" using v1, reason=FieldManagerConflict, additionalProperties={})], group=null, kind=null, name=null, retryAfterSeconds=null, uid=null, additionalProperties={}), kind=Status, message=Apply failed with 1 conflict: conflict with "different-agent" using v1: .metadata.annotations.strimzi.io/discovery, metadata=ListMeta(_continue=null, remainingItemCount=null, resourceVersion=null, selfLink=null, additionalProperties={}), reason=Conflict, status=Failure, additionalProperties={})., applying force After the forced apply, Strimzi restores the correct value of its managed annotation, while the custom annotation remains untouched: &gt; kubectl get service my-cluster-kafka-bootstrap -o jsonpath='{.metadata}' | jq { "annotations": { "my.annotation/some": "value", "strimzi.io/discovery": "[ {\n \"port\" : 9092,\n \"tls\" : false,\n \"protocol\" : \"kafka\",\n \"auth\" : \"none\"\n}, {\n \"port\" : 9093,\n \"tls\" : true,\n \"protocol\" : \"kafka\",\n \"auth\" : \"none\"\n} ]" }, ... } This example demonstrates how Server-Side Apply allows Strimzi to reliably enforce the fields it owns, while safely coexisting with other actors managing the same resource. Removal of fields In Server-Side Apply, every actor have a possibility to remove the fields - but only those they manage. That means, in case that Strimzi owns the strimzi.io/discovery annotation and we want to remove it with our different-agent field manager, the field will not be deleted after the update. Only the my.annotation/some will be removed, as it is owned by different-agent field manager: &gt; kubectl apply --server-side --field-manager=different-agent -f - &lt;&lt;EOF apiVersion: v1 kind: Service metadata: annotations: {} # set annotations to null labels: app.kubernetes.io/instance: my-cluster app.kubernetes.io/managed-by: strimzi-cluster-operator app.kubernetes.io/name: kafka app.kubernetes.io/part-of: strimzi-my-cluster strimzi.io/cluster: my-cluster strimzi.io/component-type: kafka strimzi.io/discovery: "true" strimzi.io/kind: Kafka strimzi.io/name: my-cluster-kafka name: my-cluster-kafka-bootstrap namespace: test spec: clusterIP: 10.97.174.54 clusterIPs: - 10.97.174.54 internalTrafficPolicy: Cluster ipFamilies: - IPv4 ipFamilyPolicy: SingleStack ports: - name: tcp-replication port: 9091 protocol: TCP targetPort: tcp-replication - name: tcp-clients port: 9092 protocol: TCP targetPort: tcp-clients - name: tcp-clientstls port: 9093 protocol: TCP targetPort: tcp-clientstls selector: strimzi.io/broker-role: "true" strimzi.io/cluster: my-cluster strimzi.io/kind: Kafka strimzi.io/name: my-cluster-kafka sessionAffinity: None type: ClusterIP EOF The annotations field in the Service after the apply looks like this: &gt; kubectl get service my-cluster-kafka-bootstrap -o jsonpath='{.metadata}' | jq { "annotations": { "strimzi.io/discovery": "[ {\n \"port\" : 9092,\n \"tls\" : false,\n \"protocol\" : \"kafka\",\n \"auth\" : \"none\"\n}, {\n \"port\" : 9093,\n \"tls\" : true,\n \"protocol\" : \"kafka\",\n \"auth\" : \"none\"\n} ]" }, ... } Conclusion In this blog post, we described Server-Side Apply, how Strimzi uses it, how to enable it, and how it can simplify working with Strimzi — especially in environments where multiple operators modify the same Kubernetes resources. Although Server-Side Apply has been available in Strimzi since version 0.48.0, it is still in the alpha stage and ready for broader testing. We plan to move it to beta (enabled by default) in next version - Strimzi 0.51.0. In case that you will find any issue with the implementation, or have suggestions related to Server-Side Apply in Strimzi, you can share your feedback with us on Slack, or by opening a discussion or an issue on GitHub.]]></summary></entry></feed>